How to Detect and Stop AI Ticket Routing Loops
Detect AI ticket routing loops from assignment history, repeated graph paths, and hop limits, then contain and release affected tickets safely.
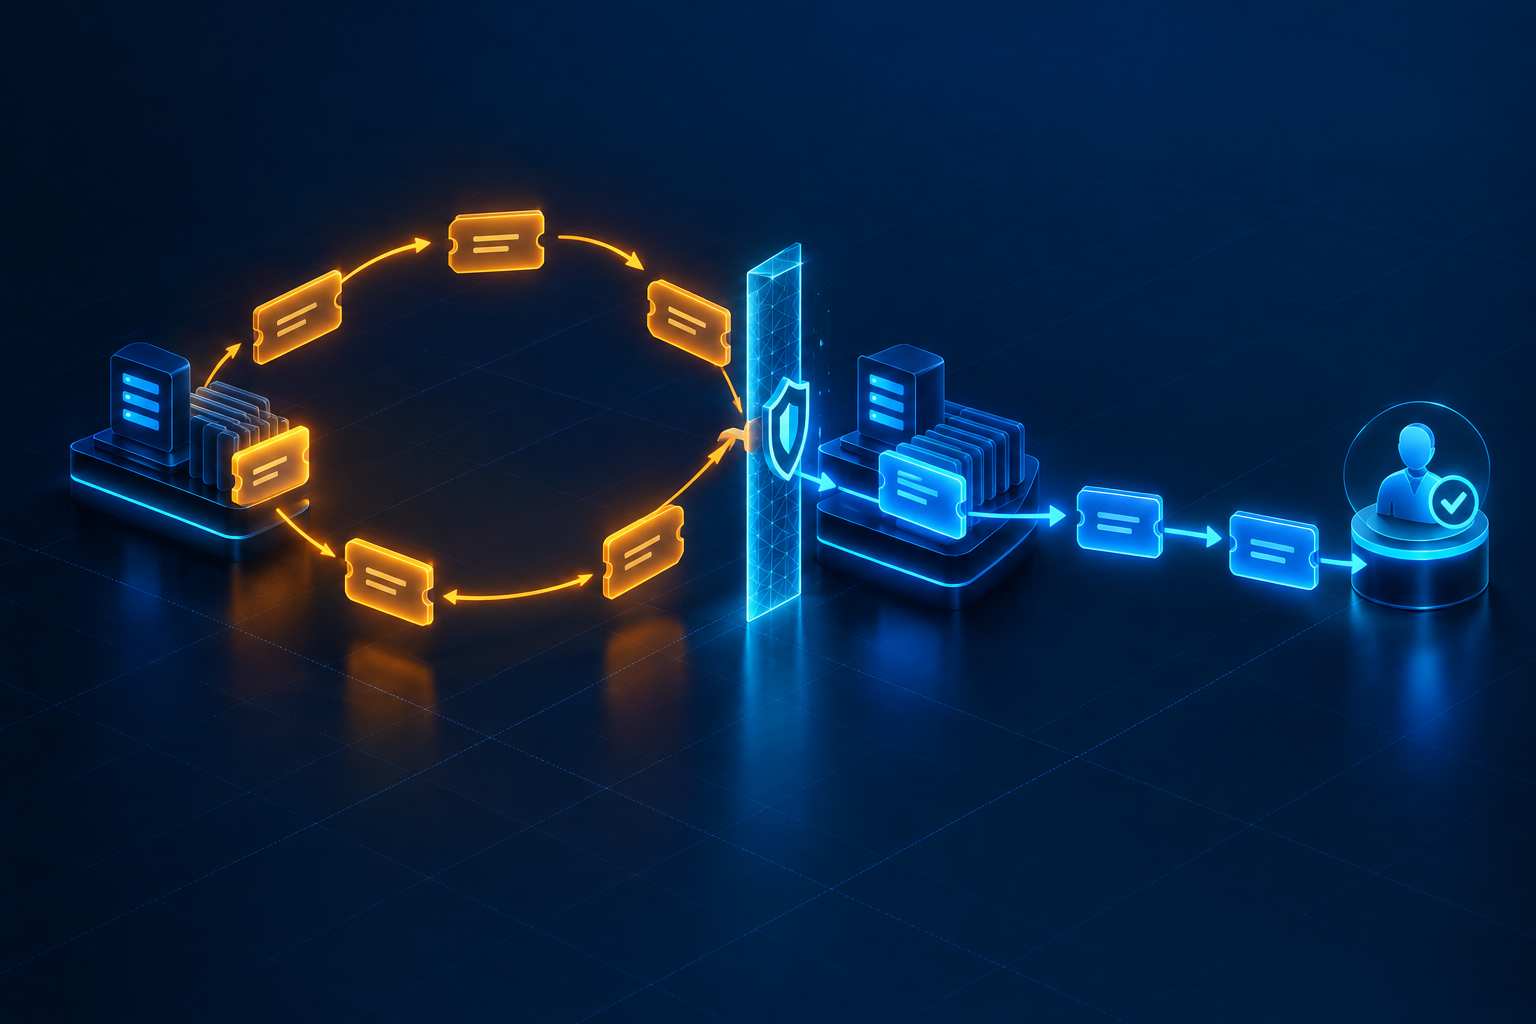
An AI ticket routing loop occurs when a ticket moves repeatedly among teams, queues, or workflow states without gaining the context or ownership needed for progress. Each individual assignment may succeed, so ordinary error monitoring can miss the condition while response time grows and accountability weakens.
This guide provides an event-based method to detect, contain, investigate, and safely release looped tickets. It supports the broader controls in AI Ticket Routing Resilience: A Practical Control Framework. Use the AI ticket triage guide for the underlying triage model, and treat recommendations from Layer8 Triage as one input to a governed assignment workflow.
Define a routing loop operationally
Do not define every reassignment as a loop. Legitimate work can move from triage to a specialist, from a specialist to an approver, or from support into an incident process.
A useful loop definition combines repeated movement with lack of meaningful progress. Indicators include:
- The ticket returns to a prior group within a fixed window.
- The same directed edge repeats, such as Team A to Team B more than once.
- Automated assignment exceeds a hard hop limit.
- The ticket re-enters fallback after controlled release.
- Two policies alternate the ticket between incompatible states.
- A group rejects ownership without adding new deciding context.
- The route repeats while service state, category, and ownership evidence remain unchanged.
Define an automated containment threshold separately from an analytical threshold. A hard hop limit can stop obvious harm. A lower-sensitivity detector can surface suspicious patterns for review without moving the ticket.
Build a complete assignment history
Current owner is insufficient. Preserve an append-only event for every routing action.
Record:
- Ticket and routing-episode identifiers
- Previous and intended destination
- Final observed destination
- Actor type: model workflow, rule, integration, or human
- Recommendation, confidence, and definition version
- Policy action and policy version
- Deciding context available at the time
- Assignment request and execution result
- Reason supplied for rejection or reassignment
- Timestamp and correlation identifier
- Whether the destination accepted ownership
Separate intended from observed destination. An integration can request one queue while a platform rule immediately moves the ticket elsewhere.
The evidence design in AI Ticket Routing Observability: A Practical Framework supports this separation. Preserve human actions in the same sequence so automated and manual handoffs can be analyzed together.
Model the route as a graph
Represent resolver groups or workflow states as nodes and assignments as directed edges. For one routing episode, the sequence might be:
Intake → Identity → Endpoint → Identity
The repeated Identity node is a cycle candidate. It becomes a likely operational loop when no relevant context changed and neither group accepted ownership.
Graph features useful for detection include:
- Repeated node count
- Repeated edge count
- Cycle length
- Time between repeated visits
- Number of unique groups
- Automated versus human actors
- Context changes between transitions
- Acceptance or work evidence at each node
A graph does not replace policy. It provides a consistent way to identify cycles longer than a simple two-team bounce.
Reset or start a new routing episode when a material event changes the problem: a user supplies requested context, an incident is declared, the ticket is split, or a resolver completes one stage and deliberately hands off the next. Document the reset rule so normal multi-stage work is not hidden or falsely flagged.
Enforce a hard automated-hop limit
Set a maximum number of automated assignments within a routing episode. When the limit is reached:
1. Stop further automated reassignment.
2. Preserve the current valid owner if one exists.
3. Create a visible loop-containment state or review task.
4. Record the route history and active policy versions.
5. Notify the accountable routing or service owner.
6. Require human acceptance or a material context change before release.
The exact number should reflect the workflow. The important control is that the limit is finite, deterministic, and tested.
Do not reset the count because a retry used a new request identifier or because the ticket briefly entered fallback. Count operational movement, not implementation calls.
Detect loops without over-alerting
Use multiple signals rather than one global reassignment count.
Repeated-edge detector
Alert when the same pair of groups repeats within one episode. This is effective for A-to-B-to-A bounces.
Repeated-node detector
Detect returns to any prior destination. This catches longer cycles such as A-to-B-to-C-to-A.
No-progress detector
Compare deciding context between hops. If category, relevant fields, service state, and ownership evidence did not change, another move is less likely to be justified.
Rapid-handoff detector
Flag transitions occurring too quickly for meaningful resolver work. Keep thresholds specific to workflow and actor type.
Fallback-return detector
Detect a ticket released from fallback that returns for the same reason or returns to the same invalid route.
Population detector
Look for many tickets following the same cycle after a release or organizational change. This can identify a systemic definition or mapping conflict before individual tickets reach the hop limit.
Segment detectors by channel, category, tenant, policy version, and resolver-group pair. Baselines for an incident-coordination workflow may differ from a routine support queue.
Contain the ticket safely
Containment should stop movement without discarding existing ownership.
If a valid human owner is working the ticket, freeze automated rerouting and create a review task. If no group has accepted ownership, move the ticket to an owned loop-review path under explicit admission rules.
The companion guide, How to Design Safe Fallback Queues for AI Ticket Routing, explains how to govern that temporary path.
During containment:
- Preserve the full event sequence.
- Prevent rules from immediately moving the ticket again.
- Show the current priority and service deadline.
- Identify the last group that accepted ownership, if any.
- Require one accountable reviewer.
- Avoid bulk reassignment until the common cause is understood.
A loop alert without an execution block can become another notification attached to a ticket that continues bouncing.
Diagnose the control conflict
Start with the route sequence and ask what made each transition appear valid.
Common causes include:
- Overlapping resolver-group definitions
- Definitions that describe tools but not ownership boundaries
- One group’s exclusion matching another group’s rejection rule
- Ticket-platform rules that override AI routing
- A stale queue mapping after organizational change
- Different policies acting on category and priority in opposite order
- Missing intake context that each group assumes another group will collect
- Retry logic interpreting a rejection as a fresh ticket
- Human macros that trigger automated reassignment
- Fallback release into the same unresolved condition
Compare the effective configuration and ticket state at every hop. Do not assume the latest definitions were active for the whole sequence.
Use How to Write Resolver-Group Definitions for AI Ticket Routing to repair ambiguous ownership boundaries. Include positive examples, exclusions, adjacent groups, and the action to take when required context is missing.
Separate recommendation from execution conflicts
A loop may occur even when the recommendation remains stable.
For example, the routing service recommends Identity on every evaluation, but a ticket-platform rule sends requests with one field value to Endpoint. Endpoint then uses a macro that invokes routing again. The visible sequence alternates even though the model output does not.
Compare:
- Recommended destination
- Policy-selected action
- Resolved platform destination
- Observed owner after execution
- Subsequent platform automation
- Human action or rejection
This layered comparison prevents unnecessary model changes when the conflict exists in platform rules or queue mappings.
Correct the ticket before correcting the system
A contained ticket still needs an owner. Assign one person or group to make the immediate ownership decision using the available evidence. Request missing information once, with a named owner for follow-up.
Record:
- The accepted destination
- Why it owns the work
- Any remaining handoff that is expected
- The policy or definition conflict found
- Whether the ticket can leave containment
- The corrective action for similar tickets
Do not wait for a full configuration release when an authorized operator can safely establish ownership for the affected ticket.
Repair the governing control
Choose the fix that matches the demonstrated cause:
- Clarify overlapping resolver-group definitions.
- Add a missing-context clarification path.
- Remove or reorder a conflicting platform rule.
- Validate destination mappings before activation.
- Add a policy exclusion for a protected workflow.
- Make retries idempotent and state-aware.
- Stop fallback release when the admission reason persists.
- Add the observed sequence to regression tests.
Manage the change through AI Ticket Routing Change Management: A Practical Control Framework. Record affected groups, expected behavior, test evidence, approval, rollout scope, and rollback conditions.
Avoid tuning only for one ticket. Add adjacent examples that should continue routing correctly so the repair does not shift the boundary and create a different loop.
Release contained tickets carefully
Before release, verify:
- A valid destination is active and authorized.
- The current ticket state has not been superseded.
- The conflicting policy, rule, or mapping is corrected or safely bypassed.
- The new route has an accountable owner.
- Hop count and containment history remain preserved.
- Monitoring can detect repeat movement.
- Release authority is recorded.
Use bounded batches for a population affected by the same conflict. Stop if tickets return to a prior node, re-enter fallback for the same reason, or fail destination acceptance.
Do not erase the routing episode after release. Start a new controlled phase while retaining the evidence that led to containment.
Alert on loop consequence
A useful loop alert identifies:
- Affected ticket and route sequence
- Repeated nodes or edges
- Hop count and elapsed time
- Current owner and acceptance state
- Ticket priority and approaching deadlines
- Actor and policy versions involved
- Last material context change
- Required containment or review action
- Related tickets following the same path
Group alerts by common route and version when a systemic condition affects many tickets. One incident with the affected population is more actionable than hundreds of isolated notifications.
Use the principles in How to Set Alerts for AI Ticket Routing Drift to combine hard safety signals with volume, persistence, and segmentation.
Measure loop risk and control performance
Track:
- Tickets reaching warning and hard hop thresholds
- Repeated edges and nodes by resolver group
- Time spent without accepted ownership
- Loops by actor type and policy version
- Fallback returns for the same reason
- Tickets corrected before the hard limit
- Time from containment to accepted ownership
- Repeat loops after corrective change
- False-positive reviews with documented reasons
Always retain denominators. A group with three looped tickets from twenty assignments may need different attention than one with three from several thousand.
Review both individual high-consequence cases and recurring low-volume patterns. Aggregate rates should not hide a protected or time-critical ticket trapped in a cycle.
Test loop controls
Create test cases for:
- Two-group bounce
- Three-group cycle
- Repeated assignment to the same group
- Human correction followed by stale automated action
- Platform rule overriding a recommendation
- Fallback release into the original condition
- Missing context with repeated reevaluation
- Legitimate multi-stage handoff
- Incident escalation that should start a new episode
- Duplicate events that should not increment operational hops
Verify containment in the actual ticket platform. A detector test is incomplete if downstream automation can continue moving the ticket after the loop flag is set.
Add confirmed production cases and nearby correct routes to the regression method in How to Test AI Ticket Routing Changes Before Production.
Example: identity and endpoint teams bounce a ticket
A ticket reports that a managed laptop repeatedly prompts for credentials after a password reset. The routing service recommends Identity because the ticket describes authentication failure. Identity sends it to Endpoint because the symptom occurs on one device. An Endpoint macro adds a device field and invokes automated routing, which recommends Identity again.
The repeated-edge detector identifies Identity → Endpoint → Identity. No new diagnostic evidence was added, and neither team accepted ownership. The workflow freezes automated movement at the hop limit and leaves the ticket in an owned review state.
Review finds that both group definitions exclude the case conditionally, but neither specifies who must collect the deciding evidence. The organization assigns Identity to validate account state first, then permits one evidence-backed handoff to Endpoint if authentication succeeds elsewhere. Definitions and the macro are updated, and the observed sequence becomes a regression case.
The fix establishes a diagnostic owner; it does not merely force all similar tickets into one queue.
Conclusion
Routing loops are successful state changes that fail to establish progress. Detect them from complete assignment history, repeated graph paths, missing context change, and bounded hop counts.
Contain movement while preserving valid ownership, diagnose the control conflict by layer, and release tickets only after the route and current state are verified. This turns an otherwise silent source of delay into a testable routing safety control.