AI Ticket Routing Resilience: A Practical Control Framework
Build resilient AI ticket routing with durable state, bounded retries, explicit degraded modes, loop containment, governed fallback, and reconciled recovery.
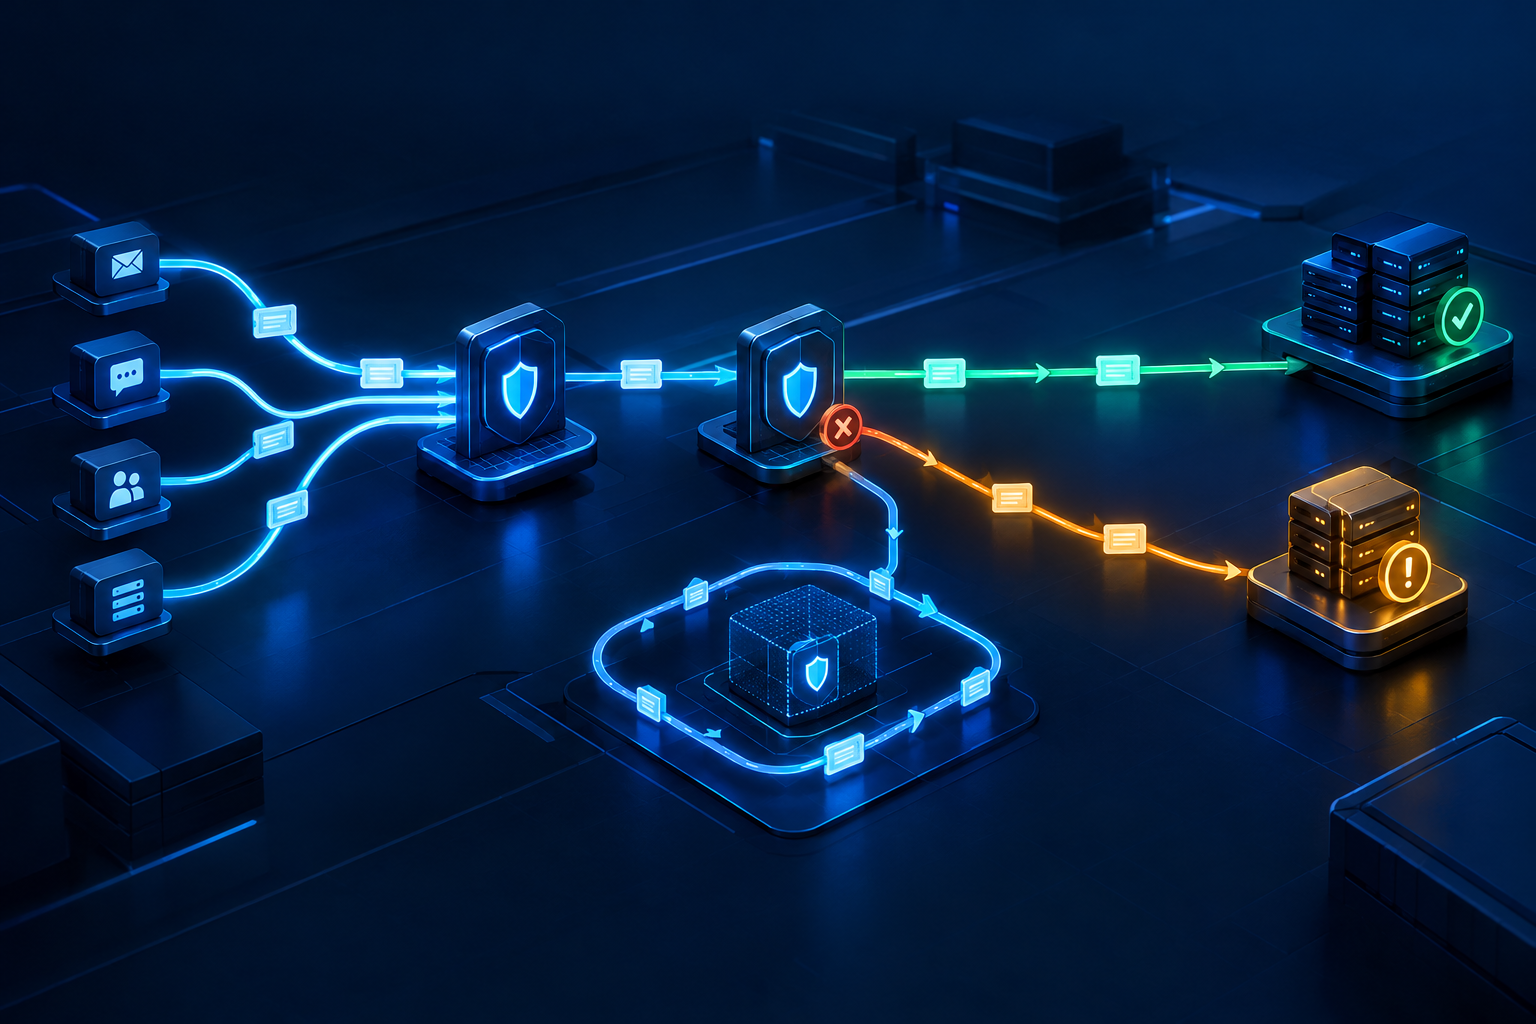
AI ticket routing resilience is the ability to keep ticket intake moving safely when a recommendation, policy, integration, or destination fails. It is not the same as maximizing model accuracy. A highly accurate routing service can still create operational harm if a queue disappears, an assignment call times out, or repeated retries bounce a ticket between teams.
Use the AI ticket triage guide as the foundation for classification, confidence, and human review. This framework focuses on the controls around those decisions: how the workflow degrades, contains faults, preserves evidence, and returns to normal operation. Layer8 Triage can provide a recommended team and confidence score, while the surrounding ticket workflow remains responsible for policy, assignment, fallback, and recovery.
Define the resilience objective
Start with the service outcome that must survive a failure. “The routing API is available” is too narrow. A useful objective describes what happens to each accepted ticket:
- The ticket receives one durable intake record.
- It reaches an eligible owner or a governed holding path.
- A failed automated action does not silently discard it.
- Repeated processing cannot create an unlimited assignment loop.
- Operators can reconstruct the recommendation, policy decision, and execution result.
- Recovery does not duplicate or skip waiting tickets.
These are safety and continuity properties. They should hold when the recommendation is uncertain, the ticket platform is degraded, a destination is invalid, or telemetry is incomplete.
Define the boundary as well. Routing resilience does not guarantee that the resolver can fix the underlying issue. It guarantees that the ticket remains visible, controlled, and recoverable while ownership is established.
Map the routing path and its failure domains
Document the complete route from intake to accepted ownership. A common path includes:
1. Receive and persist the source ticket.
2. Normalize subject, body, channel, tenant, and identifiers.
3. Request or compute a routing recommendation.
4. Apply confidence, category, entitlement, and protected-work policies.
5. Resolve the recommended group to a valid platform destination.
6. Execute the assignment.
7. Confirm that the destination accepted ownership.
8. Record the decision and execution evidence.
9. Monitor for correction, reassignment, or timeout.
Each stage has a different failure mode. Parsing can omit decisive context. Recommendation can time out. Policy can select human review. Destination resolution can return an inactive queue. Assignment can fail after the platform accepted the write but before the caller received confirmation. A team can reject ownership and send the ticket back.
Avoid treating all of these outcomes as “routing errors.” The safe response depends on where certainty was lost.
The event model in AI Ticket Routing Observability: A Practical Framework helps separate recommendation, policy, and execution. That separation is essential during partial failure because a valid recommendation does not prove that assignment succeeded.
Establish routing safety invariants
Safety invariants are conditions that should never depend on a rolling quality average.
Useful invariants include:
- Every intake identifier maps to one current routing state.
- No automated destination is used unless it is active and permitted.
- A protected category cannot bypass its required review path.
- A ticket cannot exceed the configured automated-hop limit.
- A terminal assignment failure creates a visible recovery item.
- No ticket leaves fallback until a new action is durably recorded.
- Stale configuration cannot be mixed with a new policy version without an explicit compatibility rule.
Enforce invariants close to the action. A dashboard that reports an invalid destination after the ticket vanished is evidence, not prevention.
When an invariant fails, choose a deterministic safe state: stop the affected segment, retain the current owner, or move the ticket to a controlled fallback. Do not improvise a new destination from incomplete data.
Design explicit degraded modes
A resilient workflow has more than “automation on” and “automation off.” Define modes that correspond to the evidence still available.
Suggestion mode
Return the recommendation and confidence to a human without changing ownership. Use this when model behavior is uncertain but intake and review capacity remain healthy.
Scoped fallback mode
Send only an affected category, tenant, channel, or resolver-group boundary to a governed fallback queue. This contains a localized failure without disabling safe traffic.
Retain-owner mode
Keep the current valid owner when a rerouting attempt fails. This is often safer than moving an already owned ticket into a general queue.
Queue-and-replay mode
Persist pending routing work for later execution when a downstream platform is unavailable. The replay process must be idempotent and must recheck current ticket state before writing.
Manual-only mode
Suspend automated assignments and expose the affected population to operators. Define entry authority, staffing, and exit criteria before an incident.
The companion guide, How to Design Safe Fallback Queues for AI Ticket Routing, covers queue ownership, admission rules, capacity, and release controls in detail.
Contain repeated handoffs and loops
Not every routing failure is a hard error. A ticket can move successfully while making no progress. Detect repeated transitions across automated and human actions.
Track:
- Assignment count within a time window
- Repeated edges between the same two groups
- Return to a previous group without new deciding context
- Repeated fallback admission
- Assignment followed immediately by rejection
- Recommendation version, policy version, and actor for each hop
Set a hard automated-hop limit. Once reached, freeze further automated reassignment, preserve the current state, and require an accountable review. A simple count is not enough for diagnosis, but it is a reliable containment control.
How to Detect and Stop AI Ticket Routing Loops provides an event-based detection method and a controlled release process.
Control retries and ambiguous outcomes
Retries are necessary, but an unqualified retry can duplicate work or overwrite a human correction.
Give each execution request a stable idempotency key derived from the ticket, intended action, and decision version. Before retrying:
- Check whether the destination already accepted the ticket.
- Read the current owner and routing state.
- Confirm that no human changed the ticket after the failed attempt.
- Confirm that the policy and destination remain valid.
- Stop after a bounded number of attempts.
- Move unresolved work to an operator-visible state.
Distinguish a confirmed failure from an unknown outcome. A timeout after sending an assignment request does not prove the write failed. Reconcile against the ticket platform before issuing another assignment.
Protect the fallback path from overload
Fallback is part of production capacity, not an unlimited safety net. Estimate its likely arrival rate under each failure scenario and define what happens when review demand exceeds staffing.
Track the fallback population by reason, age, criticality, and source segment. Reserve urgent handling for tickets with deterministic risk signals rather than allowing every uncertain recommendation to claim top priority.
Define admission controls such as:
- Segment-specific fallback queues
- Maximum pending age by priority
- On-call activation thresholds
- Temporary confidence-policy changes
- Intake clarification for missing required context
- Load shedding for nonessential rerouting or enrichment work
Do not solve fallback overload by relaxing protected-category gates. If capacity is exhausted, make the degraded state visible and invoke the service continuity plan.
Preserve decision and recovery evidence
For every routing attempt, retain enough information to answer:
- What ticket state was evaluated?
- Which team definitions and policy versions were active?
- What recommendation and confidence were returned?
- Which policy action was selected?
- Which destination was resolved?
- What execution request was made?
- Did the destination accept ownership?
- Was the action retried, corrected, or superseded?
- Why did the ticket enter or leave a degraded mode?
Use stable event identifiers and timestamps. Preserve the original evidence when a human corrects the route; do not overwrite it with the final state.
This evidence supports both active response and the review process in How to Conduct an AI Ticket Routing Post-Incident Review.
Recover by reconciliation, not assumption
Restoring a dependency does not recover the waiting ticket population. Reconcile expected routing work against observed ticket state.
Classify each affected ticket:
- Correctly assigned and accepted
- Assigned but not accepted
- Waiting in fallback
- Pending with an unknown execution outcome
- Superseded by a human action
- Closed or merged while waiting
- Blocked by invalid destination or policy
- Safe to replay
Replay only the eligible group. Preserve human changes, use bounded batches, and stop when safety signals deteriorate. Verify both system state and operational ownership before declaring recovery.
The AI ticket routing incident-response framework provides the broader declaration, containment, communication, and closure process.
Test resilience as a system property
A unit test for the recommendation engine cannot prove routing resilience. Exercise the boundaries between components.
Include scenarios for:
- Recommendation timeout before and after request acceptance
- Missing or malformed intake fields
- Inactive, renamed, and unauthorized destinations
- Assignment success with a lost response
- Duplicate delivery of the same intake event
- Human reassignment during an automated retry
- Fallback queue saturation
- Repeated two-group and multi-group loops
- Telemetry delay or loss
- Recovery with a mixed waiting population
Use the release controls in How to Test AI Ticket Routing Changes Before Production. Run representative tests in shadow or assisted mode, then verify the actual ticket-platform state rather than only the routing service response.
Measure resilience without hiding unsafe cases
Useful measures include:
- Tickets without a durable routing state
- Assignment failures by stage and destination
- Unknown execution outcomes
- Fallback arrivals, exits, age, and reason
- Tickets exceeding the automated-hop limit
- Time from intake to accepted ownership
- Replay attempts and superseded actions
- Recovery population reconciled versus outstanding
- Time spent in each degraded mode
Segment by tenant, channel, category, policy version, and destination. A low aggregate failure rate can hide a complete outage for one queue.
Use service-level measures alongside invariants. The average time to assignment is informative, but one lost protected ticket still requires investigation.
Example: destination mapping changes during a release
A service desk renames an application-support queue. The routing definitions still recommend the correct team, but the ticket-platform mapping points to the retired destination.
Preflight validation blocks the invalid destination. Tickets for that segment enter a scoped fallback queue, while unrelated routing continues. Each fallback item records the recommendation, failed mapping, and policy version.
Operators correct the mapping and validate it with representative tickets. Recovery logic reads the current state of every fallback ticket, excludes tickets already reassigned by humans, and replays the remaining population in bounded batches. Monitoring confirms accepted ownership and stable fallback age before normal mode resumes.
The recommendation model did not fail. Resilience controls prevented an execution dependency from becoming lost work.
Implement the framework in controlled stages
Start with the most consequential failure paths.
1. Map the routing stages and durable states.
2. Define safety invariants and terminal failure behavior.
3. Add idempotent execution and outcome reconciliation.
4. Establish one owned fallback path with capacity limits.
5. Detect and contain repeated handoffs.
6. Instrument degraded-mode entry, population, and exit.
7. Test dependency failures and mixed-state recovery.
8. Add the controls to the AI ticket routing change-management framework.
Assign owners for routing policy, ticket-platform integration, fallback operations, and incident authority. A control without an operator and a verification method will not be dependable under failure.
Conclusion
AI ticket routing resilience comes from controlled state transitions, not from confidence scores alone. A production workflow needs durable intake, valid destinations, bounded retries, explicit degraded modes, loop containment, owned fallback capacity, and reconciled recovery.
Build those controls around the routing decision before increasing automation. The result is a system that can fail visibly, preserve operational ownership, and recover without creating a second incident from the waiting ticket population.