How to Set Alerts for AI Ticket Routing Drift
Design production alerts for routing drift using safety invariants, segmented baselines, minimum volumes, severity, and response runbooks.
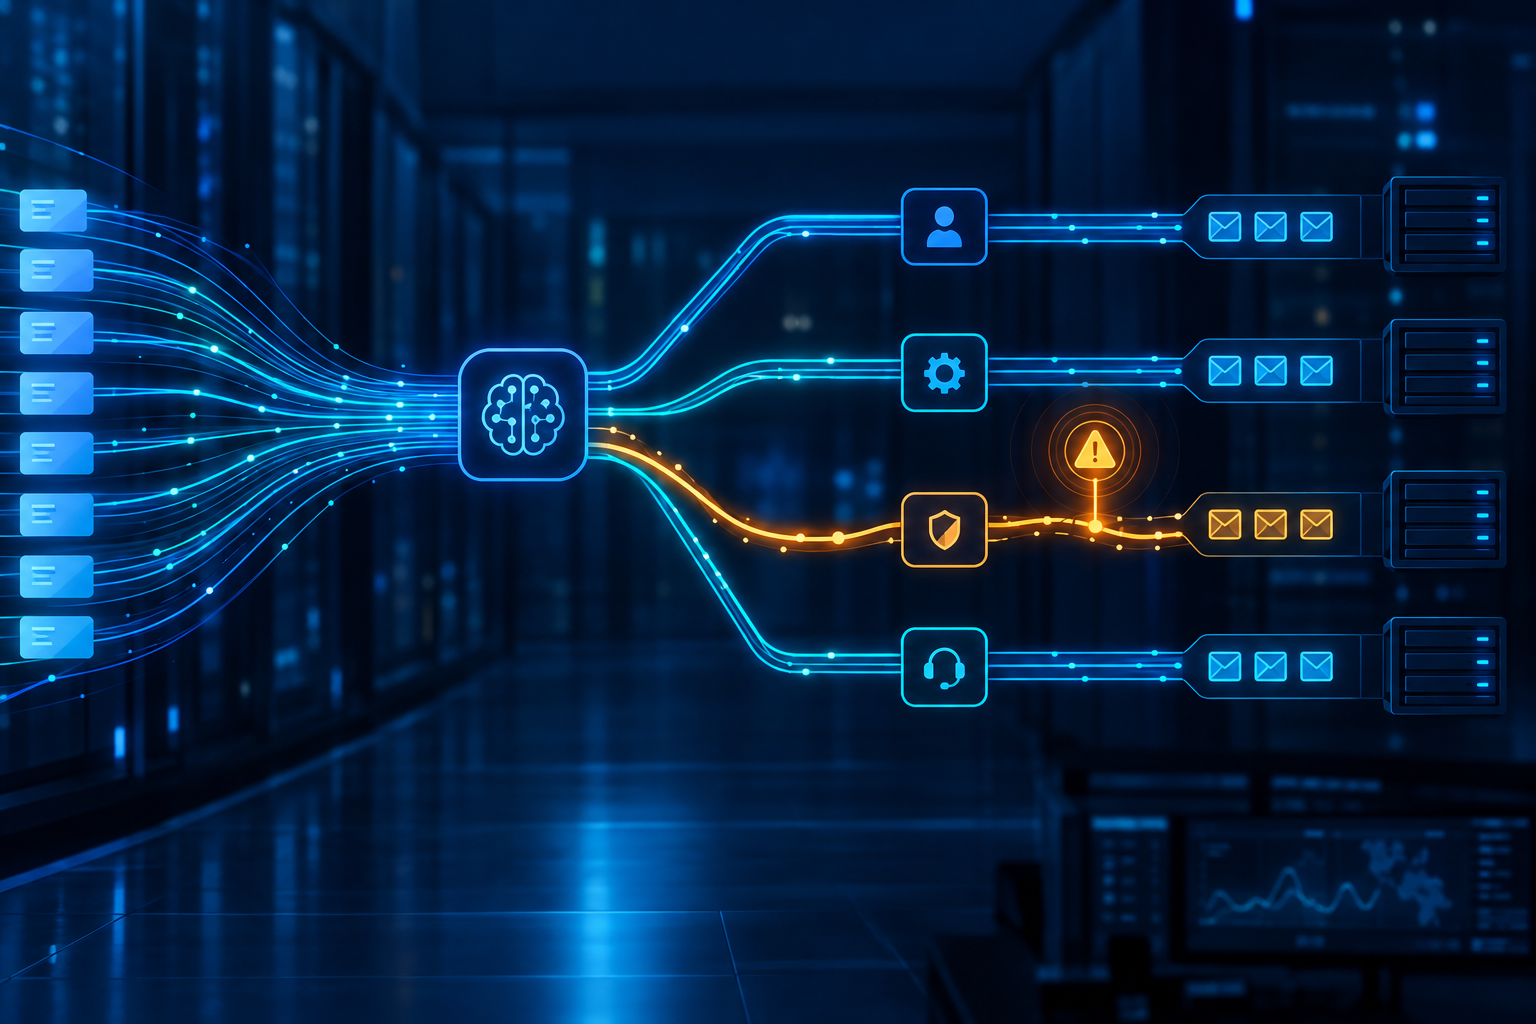
AI ticket routing drift is a sustained change in production behavior that can weaken assignment quality or move the workflow outside its approved operating boundary. Drift may appear in ticket language, service mix, group ownership, intake context, confidence, policy actions, or queue outcomes.
An alerting program should detect those changes early enough for an owner to investigate, without turning ordinary traffic variation into noise. This guide applies the AI ticket routing observability framework to alert design and uses the investigative views described in how to build an AI ticket routing quality dashboard.
It complements the broader AI ticket triage guide and the controlled routing workflows available through Layer8 Triage.
Define drift in operational terms
Do not define drift as any statistical difference from a prior period. Define it as a change that affects a routing decision or safety control.
Useful drift classes include:
Input drift
Ticket language, category mix, channel, user population, or required-field availability changes. A new portal, acquired business unit, product launch, or incident can create input drift.
Ownership drift
Service boundaries or resolver responsibilities change while routing definitions remain static. Tickets may be linguistically familiar but operationally belong somewhere new.
Recommendation drift
The distribution of recommended groups, confidence bands, or alternatives changes without an expected business cause.
Policy-action drift
The balance of automatic assignment, review, hold, fallback, and block changes. This can happen when confidence moves or when a policy, exclusion, or context gate changes.
Outcome drift
Confirmed misroutes, high-confidence corrections, repeated reassignments, or time to accepted ownership changes in a segment.
System drift
Timeouts, missing enrichment, stale definitions, invalid queue mappings, or event-pipeline failures alter behavior even when the recommendation logic is stable.
Classifying drift this way directs the investigation. A rise in fallback caused by missing application names should not trigger the same response as high-confidence assignments to the wrong identity queue.
Start with safety invariants
Some conditions should alert immediately because they represent control failure, not a trend.
Examples include:
- A protected category bypasses mandatory review
- An automatic assignment targets an inactive or unauthorized queue
- A routing failure leaves a ticket without an owner
- The active configuration version is not approved
- Required audit fields are absent
- A rollback or fallback path fails
- A critical-impact ticket is assigned contrary to an explicit ownership rule
These alerts may fire on one event. Give them a clear severity, owner, containment action, and evidence link.
Do not use a broad confidence threshold as a substitute for these controls. The guide on how to set auto-routing confidence thresholds explains how scores combine with category risk and non-score gates.
Choose drift indicators by layer
After safety invariants, choose indicators that represent meaningful behavior.
Input indicators
- Category and requested-service distribution
- Intake channel mix
- Required-field completion
- Unknown service or asset values
- Language or region mix when relevant
- Ticket volume by segment
Recommendation indicators
- Recommended group distribution
- Confidence-band distribution
- No-recommendation or ambiguous result rate
- Alternative-candidate proximity when available
- Recommendation changes for a stable evaluation set
Policy indicators
- Automatic assignment share
- Assisted-review share
- Fallback and hold share
- Exclusion and override activations
- Review queue volume and age
Outcome indicators
- Confirmed misroutes among reviewed cases
- Harmful automatic assignments
- High-confidence corrections
- Corrections by adjacent group pair
- Reassignment loops
- Time to accepted owner
System indicators
- Routing errors and timeouts
- Enrichment availability
- Queue mapping failures
- Event lag and missing events
- Configuration mismatch
Select a small set that has an owner and response. Keep exploratory indicators on the dashboard until their operational meaning is established.
Establish a baseline that matches the traffic
A baseline should represent comparable operation.
Segment baselines by the dimensions that materially affect routing:
- Resolver group or adjacent group pair
- Category and requested service
- Intake channel
- Day or shift when traffic differs
- Automatic versus reviewed action
- Configuration version
- Planned campaign, release, or seasonal period
Avoid comparing a post-release Monday with a quiet weekend average. Also exclude known data outages and one-time migration traffic from the stable baseline unless that traffic is expected to recur.
Document the baseline window, exclusions, expected traffic cycle, and minimum sample. A baseline is an operational reference, not permanent truth. Reassess it after an approved service or ownership change has stabilized.
Combine magnitude, persistence, and volume
A practical drift condition usually needs three elements:
1. Magnitude: the change is large enough to matter.
2. Persistence: the change lasts beyond a brief fluctuation.
3. Volume: enough relevant events exist to support action.
For example, an alert might require a fallback share to exceed the segment's expected range for several evaluation windows and involve a minimum number of tickets. The exact values must come from the organization's traffic and risk tolerance.
Safety invariants are the exception. One unauthorized automatic assignment can be actionable regardless of volume.
Use separate conditions for high-volume and low-volume segments. In a low-volume protected category, event review may be safer than waiting for a statistically stable trend.
Use severity based on consequence
Map severity to the required response.
Critical
A hard safety control failed or tickets may be silently unowned. Contain immediately by disabling the affected automatic path, forcing review, activating fallback, or rolling back the change.
High
Evidence suggests harmful automatic routing or a material boundary failure. Notify the routing owner and affected service owner, restrict the affected segment if necessary, and begin investigation.
Medium
A persistent change in action mix, confidence, correction pattern, or intake completeness needs review during the operating window. Automation may continue if safety controls remain effective.
Informational
A planned or low-risk shift should be recorded and reviewed but does not require interruption.
Severity should not depend only on percentage movement. A smaller change in a privileged-access queue can have greater consequence than a larger change in a general information queue.
Control alert noise
Routing data is uneven. Use mechanisms that preserve sensitivity without overwhelming operators.
- Require minimum event counts for rate alerts.
- Use consecutive windows for persistent conditions.
- Group related alerts by group, category, version, and cause.
- Suppress child symptoms when a known upstream failure explains them.
- Add maintenance windows for approved releases while preserving safety-invariant alerts.
- Use cooldowns after acknowledgement, not indefinite suppression.
- Route low-volume anomalies to a review list when paging is not justified.
- Close alerts only after the metric and cause are understood.
Track alert quality. Record whether each alert was actionable, expected, duplicate, data-related, or incorrectly configured. Alert rules need their own feedback loop.
Attach a runbook to every alert
An alert without a response path only transfers uncertainty to the operator.
Each runbook should state:
- What condition fired
- Which segment and configuration version are affected
- Why the condition matters
- Which dashboard view and events to inspect
- How to verify data freshness
- Immediate containment options
- Investigation owner and service owner
- Escalation and communication path
- Closure evidence
- Follow-up regression or monitoring requirement
The testing process in How to Test AI Ticket Routing Changes Before Production can supply regression cases for the affected boundary. The release controls in AI Ticket Routing Change Management: A Practical Control Framework should define rollback authority before the alert occurs.
Use a standard investigation sequence
When a drift alert fires:
1. Confirm the event stream and dashboard are current.
2. Identify the affected group, category, channel, action, and version.
3. Check for approved releases, service launches, incidents, or ownership changes.
4. Compare automatic and reviewed outcomes.
5. Inspect the changed event set and correction labels.
6. Determine whether the source is input, ownership, recommendation, policy, outcome, or system drift.
7. Contain risk at the narrowest safe scope.
8. Create targeted regression cases and correct the responsible layer.
9. Validate the correction in shadow or controlled operation.
10. Monitor the segment and document closure.
Do not begin by moving a threshold. A threshold change may reduce automatic assignments, but it can also hide a broken intake field, stale queue mapping, or unresolved ownership boundary.
Example: confidence rises while quality falls
Suppose the high-confidence share for Network Operations rises over three days. At the same time, corrections from Network Operations to Endpoint Support increase. Ticket volume is normal, and no routing release is recorded.
The alert groups the two signals for the Network–Endpoint boundary. Event review shows a new remote-access client version. Users describe client installation failures as network connection errors, and the existing group definitions contain broad VPN language.
The immediate response is to require review for the affected remote-access category. The durable response is to:
- Add client version and connection stage to intake enrichment
- Clarify local-client failure exclusions in the Network definition
- Add positive and negative examples to both group definitions
- Test paired client-failure and connected-but-unreachable cases
- Restore automatic assignment only after controlled evidence supports it
The issue involved input and ownership evidence, not an arbitrary decline in model confidence.
Example: fallback grows after an intake change
A portal release removes a structured requested-service field. The missing-context gate correctly sends affected tickets to fallback. A medium-severity alert fires after the change persists across the required windows and exceeds the minimum event volume.
The operator verifies that recommendation quality is stable for tickets where the field remains present. The team restores the field and keeps the context gate. After the event stream confirms normal field completion and fallback returns to its baseline range, the alert closes.
The alert protected the workflow from silent misrouting while pointing investigation to intake.
Test alerts before enabling production response
Validate each alert with historical replay, synthetic events, or a controlled environment.
Test:
- A true condition crossing the threshold
- A brief spike that should not fire
- A low-volume rate change
- A known release annotation
- Missing or delayed telemetry
- Duplicate events
- An upstream integration failure that causes several symptoms
- A safety invariant involving one event
- A recovery and closure sequence
Verify recipients, evidence links, suppression, escalation timing, and runbook accuracy. An alert that reaches the wrong owner is an operational defect.
After a routing change, monitor the affected alert rules as part of release verification. Changes to definitions or policy can alter the expected action mix even when quality improves.
Connect alerts to controlled automation
Layer8 Triage can support confidence-aware routing, human review, and structured decisions. Alert response can use those controls to narrow automation for an affected segment while preserving normal operation elsewhere.
Keep automatic containment deliberate. Sending a segment to review can be appropriate when a hard safety condition fails. Automatically changing definitions or thresholds in response to a drift signal introduces a new unreviewed routing change and should not be the default.
Conclusion
Useful AI ticket routing drift alerts are built around operational consequences. Start with hard safety invariants, then monitor input, recommendation, policy, outcome, and system indicators against comparable baselines.
Combine magnitude, persistence, and volume for trend alerts; use consequence for severity; and attach every alert to an owner, evidence, containment option, and runbook. The result is an alerting layer that exposes meaningful production change without converting normal queue variation into noise.
<!-- zero-content-links:start -->
Related Layer8 Labs guides
- AI Ticket Routing Incident Response: A Practical Operating Framework
- How to Build an AI Ticket Routing Incident Runbook
- Explore Layer8 Triage
<!-- zero-content-links:end -->