AI Ticket Routing Change Management: A Practical Control Framework
A practical framework for changing AI ticket routing definitions, policies, and workflows without introducing silent misroutes or queue disruption.
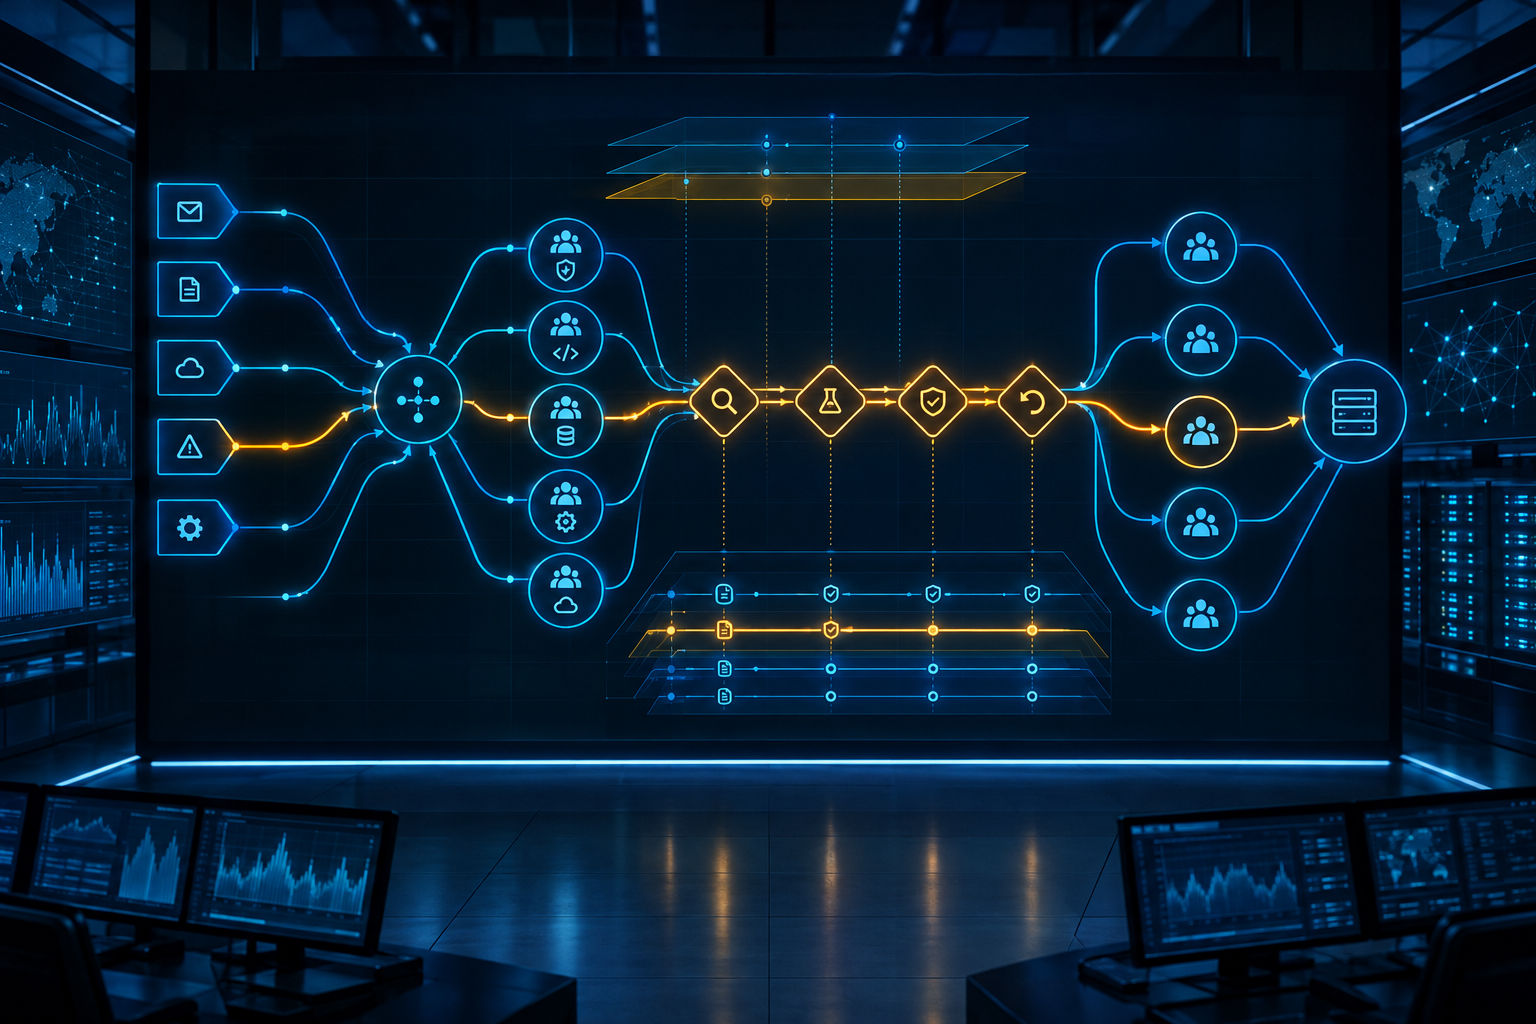
AI ticket routing changes are operational changes. A revised resolver-group description, a new exclusion rule, or a lower automation threshold can alter ownership across thousands of future tickets.
The dangerous changes are not always large. A single sentence added to a team definition can create overlap with another queue. A new service can introduce language that resembles an existing category. A workflow rule can correctly interpret a recommendation but apply it to the wrong ticket population.
The AI ticket triage guide explains the broader routing system. This article focuses on controlling changes to that system: what must be versioned, how to test it, how to release it, and when to roll it back.
Treat the routing configuration as a production dependency
A routing system includes more than a model. Its effective behavior comes from several connected objects:
- Resolver-group names and definitions
- Ticket fields and text supplied for analysis
- Preprocessing and enrichment rules
- Recommendation and confidence outputs
- Category-specific automation thresholds
- Exclusions and mandatory review gates
- Assignment workflow logic
- Fallback queues and escalation paths
A change to any one of these objects can change the final destination. Change management must therefore evaluate the complete decision path, not only whether the recommendation looks reasonable.
For the policy layer around confidence bands and human review, use the confidence-based AI ticket triage governance framework. The change process described here supplies the release discipline around that policy.
Define the unit of change
Every proposed change needs a short record that states exactly what will be different. Avoid requests such as "improve network routing" or "fix the application queue." They are too broad to test and too vague to audit.
A useful change record contains:
- The configuration object being changed
- Current and proposed values
- The problem demonstrated by production examples
- Ticket populations expected to move
- Ticket populations expected to remain stable
- The change owner and approver
- Test evidence required before release
- Release scope and observation period
- Rollback condition and previous known-good version
Keep related edits in one change only when they solve the same routing problem. If a team definition, threshold, and intake form all change at once, the test must distinguish their effects. Otherwise, split them into sequential releases.
The companion article on how to write resolver-group definitions for AI ticket routing provides a structured definition format that makes these changes easier to compare.
Establish a baseline before editing
A change cannot be evaluated without a stable view of current behavior. Build the baseline from recent, representative traffic rather than a handful of memorable failures.
Capture:
- Initial assignment accuracy by ticket category
- Recommendation distribution by resolver group
- Confidence distribution by category and route
- Manual-review and fallback rates
- Reassignment rate with valid fulfillment handoffs excluded
- High-confidence misroutes
- Time from intake to accepted ownership
- Queue volume by group and time period
Also preserve examples for the specific boundary being changed. If Endpoint Support and Business Applications overlap, collect correctly routed and misrouted tickets from both sides. Include ambiguous tickets and requests missing important fields.
The baseline has two purposes. It shows whether the change solves the stated problem, and it exposes collateral movement elsewhere. A local improvement is not successful if it silently shifts unrelated work into the wrong queue.
The workflow in How to Audit AI Ticket Misroutes and Build a Triage Feedback Loop is a practical source of correction records and root-cause labels for this baseline.
Classify the risk of the proposed change
Not every edit needs the same release process. Assign a risk tier based on potential reach and reversibility.
Low-risk changes
Examples include correcting an obvious typo, clarifying a unique product name, or adding a positive example that does not overlap another group.
Low-risk changes still require a regression check and version record. They can usually move through a short observation window.
Medium-risk changes
Examples include changing boundaries between two teams, adding a new resolver group, modifying required context, or changing a category-specific review rule.
These changes need boundary-focused tests, shadow evaluation on current traffic, and a staged release.
High-risk changes
Examples include lowering a global auto-routing threshold, replacing the team taxonomy, changing the text supplied to the classifier, or altering fallback behavior across the service desk.
High-risk changes require broad regression coverage, workflow simulation, explicit approval, a limited initial population, and a tested rollback path.
Risk is determined by plausible operational impact, not by the number of edited lines.
Use one controlled change lifecycle
A consistent lifecycle makes evidence comparable and prevents urgent requests from bypassing necessary checks.
1. Diagnose the routing problem
Start with corrected production tickets. Assign a root cause: unclear ownership, overlapping definitions, missing intake context, stale service ownership, recommendation error, or policy error.
Do not edit a resolver definition when the decisive field never reached the routing system. Do not lower a threshold to compensate for stale ownership data.
2. State the expected behavior
Write testable expectations before making the edit.
For example:
- Password resets for managed employees should route to Identity Operations.
- Access requests for a business application should remain with Application Support.
- Tickets without an application name should enter assisted review.
- Existing endpoint-enrollment tickets should not move.
These statements become acceptance criteria.
3. Create a candidate version
Version the complete effective configuration, including definitions, preprocessing, thresholds, gates, and workflow mappings. A definition version without the associated policy version cannot reconstruct the decision.
Record the reason for the change and link the candidate to its test set.
4. Test recommendations and actions
A recommendation test asks whether the preferred team changed correctly. An action test asks what the workflow would do with the team, score, ticket fields, and current policy.
Both matter. A correct recommendation can still produce an unsafe automatic assignment if an exclusion rule is missing. A weak recommendation can be operationally contained by a review gate.
Use the detailed process in how to test AI ticket routing changes before production to build the regression set, shadow comparison, and release evidence.
5. Approve against explicit gates
Approval should answer four questions:
1. Did the targeted error pattern improve?
2. Did protected ticket populations remain within tolerance?
3. Did review, fallback, or queue volume change as expected?
4. Can the prior version be restored quickly?
An approver should see changed outcomes and operational impact, not only the edited configuration text.
6. Release in stages
Start with a bounded population. Scope by category, channel, region, business unit, or percentage of eligible tickets. Keep high-impact categories in review until the candidate has enough real traffic to evaluate.
Do not combine a routing change with unrelated workflow or staffing changes during the observation period. That makes the result difficult to interpret.
7. Monitor and close
Compare candidate behavior with the baseline. Review targeted boundary errors, high-confidence misroutes, fallback volume, manual-review load, assignment distribution, and time to ownership.
Close the change only when the observation period has covered the expected traffic pattern. A few quiet hours may be insufficient for categories concentrated around weekly access reviews or release windows.
Separate release gates from monitoring signals
Release gates are conditions that must pass before wider exposure. Monitoring signals show whether the released change remains healthy.
Useful release gates include:
- No known high-impact ticket in the regression set is auto-routed incorrectly
- Targeted boundary accuracy improves
- Protected categories remain within their accepted tolerance
- Workflow simulation applies all mandatory review gates
- Fallback behavior works when required context is absent
- Rollback restores the prior outcome set
Useful monitoring signals include:
- Resolver-group volume shift
- First-owner correction rate
- High-confidence error rate
- Review yield
- Fallback and unassigned rates
- Time to correction
- Ticket age in affected queues
A signal crossing a warning level may trigger investigation. A rollback condition should be narrower and explicit.
Define rollback before release
Rollback is not "change it back if people complain." Specify measurable triggers and the exact version to restore.
Possible triggers include:
- A critical ticket class reaches an unauthorized team
- High-confidence misroutes exceed the approved boundary
- An affected queue receives an unsustainable volume increase
- Mandatory review is bypassed
- Required fields are dropped before analysis
- Assignment actions fail while recommendations continue
Keep the prior complete configuration deployable. If rollback depends on reconstructing several manual edits, recovery will be slow and error-prone.
After rollback, preserve the candidate results. They are evidence for the next diagnosis, not a reason to erase the failed test.
Example: introducing a Cloud Platform resolver group
A service desk creates a Cloud Platform team. Historically, cloud access and runtime incidents were distributed across Infrastructure, Identity Operations, and Application Support.
The proposed change adds a Cloud Platform definition and updates the three adjacent definitions. The team first identifies expected movements:
- Cloud account provisioning moves from Infrastructure to Cloud Platform.
- Cloud console login failures remain with Identity Operations.
- Application defects running on cloud infrastructure remain with Application Support.
- Requests without an account, service, or application identifier enter review.
The regression set includes examples from all four outcomes. The candidate performs well on clear provisioning requests but pulls application errors into Cloud Platform whenever the ticket mentions a cloud provider.
The team changes the definition to distinguish platform ownership from application ownership and adds negative examples for application behavior. A second test passes the boundary cases. Shadow traffic shows a large review increase because the account identifier is often missing.
Instead of weakening the boundary, the service desk adds the identifier to the intake form and keeps incomplete requests in review. The release begins with one business unit. Queue distribution and corrections remain stable during the observation period, so the team expands the change.
This sequence treats the definition, intake data, and workflow policy as one controlled routing system.
Assign clear ownership
Routing controls often fail between organizational boundaries. Assign ownership by object:
- Service desk process owner: taxonomy and operating policy
- Resolver-group owner: team scope and boundary accuracy
- Intake owner: required fields and enrichment
- Automation owner: thresholds, gates, and assignment logic
- Configuration owner: versions, testing, deployment, and rollback
- Queue manager: production monitoring and correction workflow
One person may hold several roles, but each responsibility must be explicit. Resolver teams should approve their own scope and any boundary that can send them work.
How Layer8 Triage fits into the control framework
Layer8 Triage analyzes ticket subject and body against configured team definitions and returns a recommended team with a confidence score.
Use those outputs as inputs to a governed workflow:
1. Version the team definitions sent to the routing service.
2. Store the returned recommendation and confidence with the ticket.
3. Apply category rules, exclusions, and confidence bands.
4. Preserve the resulting action and any reviewer correction.
5. Compare candidate and current configurations on the same tickets.
6. Expand automation only after the complete action path passes its gates.
The product can support the recommendation step; the service desk remains responsible for team boundaries, intake quality, and the policy that decides when a recommendation may change ownership.
Common change-management failures
Editing production definitions directly
Direct edits remove the candidate stage and make comparison difficult. Use versioned candidates with a known release time.
Testing only known misroutes
A change can fix the reported tickets while breaking common traffic. Include protected examples that must not move.
Looking only at aggregate accuracy
Aggregate results can hide a severe failure in a low-volume category. Review boundary and impact segments separately.
Releasing a definition without its workflow policy
The operational result depends on thresholds, exclusions, and fallback actions. Test the complete decision.
Treating rollback as failure
Rollback is a control working as designed. The real failure is leaving a harmful candidate active because restoration was not prepared.
Conclusion
AI ticket routing change management connects configuration edits to operational evidence. Define the exact change, preserve a baseline, test recommendations and workflow actions, release to a bounded population, and monitor against explicit rollback conditions.
The objective is not to prevent change. It is to make routing changes observable, reversible, and attributable. That discipline lets the service desk improve definitions and automation without turning production queues into the test environment.