How to Design Safe Fallback Queues for AI Ticket Routing
Design AI ticket routing fallback queues with explicit admission rules, accountable ownership, capacity limits, and evidence-based release controls.
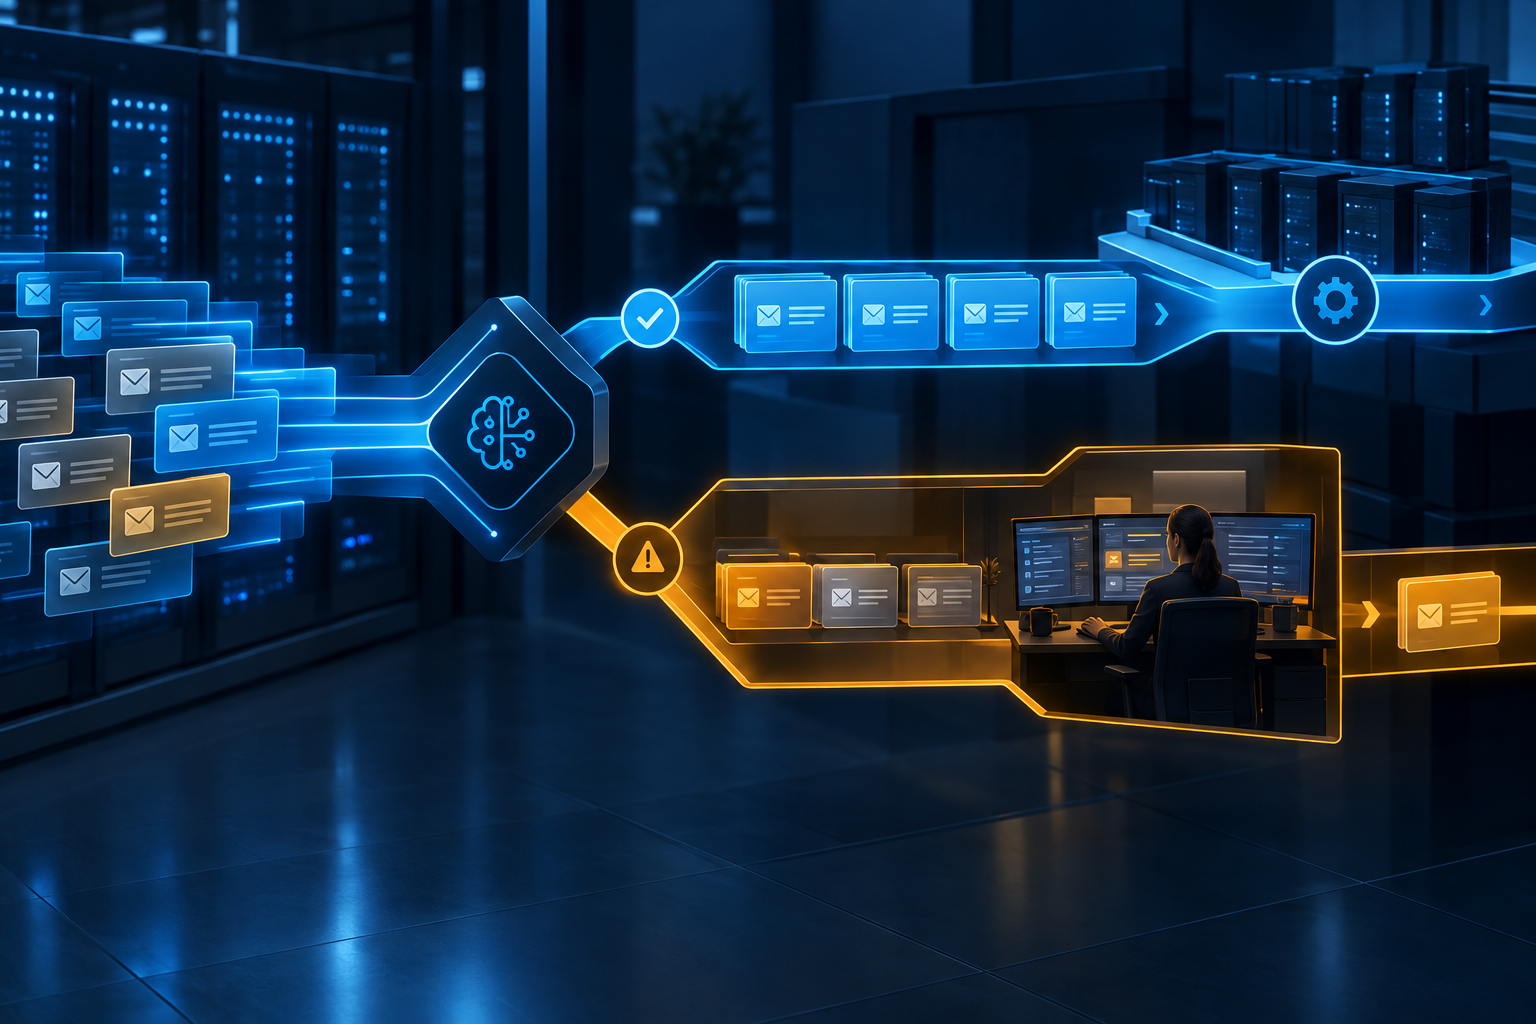
A fallback queue is the controlled destination for tickets that cannot safely complete their normal automated routing path. It should preserve visibility and ownership while operators resolve uncertainty. It should not become a permanent general queue, a silent error bucket, or a way to bypass routing policy.
This guide extends the resilience controls in AI Ticket Routing Resilience: A Practical Control Framework. Use the AI ticket triage guide for the underlying classification and confidence model. A recommendation and confidence score from Layer8 Triage can inform the routing decision, but the ticket workflow must decide when fallback is required and how the ticket leaves it.
Define the purpose of each fallback queue
Create a fallback queue for a specific operational condition, not for every ticket the workflow does not understand.
Common purposes include:
- Low-confidence recommendations requiring human selection
- Missing context that prevents a safe decision
- Invalid or unavailable destination mappings
- Protected categories requiring mandatory review
- Ticket-platform assignment failures
- A scoped routing segment placed in degraded mode
- Tickets contained after exceeding a handoff limit
These states need different owners and actions. A low-confidence ticket may need a triager to choose a team. An invalid destination needs platform or service-ownership correction. Combining both populations without reason codes hides the work required.
Use separate queues when the ownership or response differs materially. If queue proliferation would fragment staffing, use one physical queue with required reason, segment, and action fields plus filtered operational views.
Set explicit admission rules
Every fallback admission should be driven by a deterministic rule. Record the rule identifier and the evidence that triggered it.
Examples include:
- Confidence falls inside the configured review band.
- A required intake field is absent after enrichment.
- The recommended destination is inactive or unauthorized.
- The assignment request reaches its retry limit.
- The routing segment is under an approved containment action.
- The ticket reaches the maximum automated-hop count.
- Policy requires review for the detected category.
Do not route to fallback merely because an exception occurred. Classify whether the outcome is failed, unknown, or safely deferred. If an assignment request timed out after transmission, first reconcile the current owner. The ticket may already be assigned.
Admission should be idempotent. Reprocessing the same event must update the existing fallback record rather than add a duplicate item or reset its age.
Preserve the current safe state
Fallback behavior depends on whether a ticket already has an accepted owner.
For a new unowned ticket, fallback can become the temporary operational owner. For an already owned ticket, retaining the current valid owner is often safer than moving it to a central queue. Create a review task or fallback state without stripping ownership.
Define precedence rules:
1. Preserve a valid human assignment made after the automated decision.
2. Preserve an accepted resolver unless policy requires containment.
3. Do not overwrite a protected-workflow destination with a general fallback.
4. Freeze automated reassignment after a loop or hop-limit event.
5. Require explicit authority for bulk movement.
This prevents the safety mechanism from undoing useful human work.
Make every fallback item actionable
A fallback item should tell an operator why it is present and what decision is required.
Retain:
- Ticket identifier and source channel
- Current owner and assignment state
- Recommended team and confidence
- Active policy and definition versions
- Fallback reason and first admission time
- Previous destinations and actors
- Missing or conflicting context
- Execution attempts and last confirmed outcome
- Required operator action
- Escalation deadline
- Recovery eligibility
Expose the original ticket alongside the structured decision record. Avoid forcing the operator to reconstruct the failure from application logs.
The event structure in AI Ticket Routing Observability: A Practical Framework provides a useful basis for keeping recommendation, policy, and assignment evidence separate.
Assign ownership and response targets
Name an accountable owner for the queue and an owner for each admission reason. These may differ.
For example:
- Service desk triage owns low-confidence review.
- Ticket-platform operations owns assignment failures.
- Service owners resolve invalid destination mappings.
- Security operations owns protected security categories.
- Routing operations owns policy or configuration failures.
Set response targets from ticket consequence and queue age, not one universal fallback SLA. A suspected account-compromise ticket and a routine software request should not receive the same response order merely because both need review.
Define shift coverage, escalation contacts, and authority to change routing mode. A queue that exists only on a dashboard but has no staffed owner is not a fallback control.
Plan capacity before activation
Estimate fallback load for realistic failure scenarios:
- One resolver-group mapping fails.
- A source channel omits required fields.
- Recommendation service is unavailable.
- A policy release moves a segment into review.
- The primary ticket platform is degraded.
- Loop detection contains a burst of tickets.
For each scenario, estimate arrivals, review time, available operators, and maximum acceptable age. The purpose is not a precise forecast. It is to identify when the proposed fallback path will become the next bottleneck.
Define capacity actions in advance:
- Add cross-trained reviewers.
- Narrow containment to the affected segment.
- Pause nonessential rerouting.
- Request missing information at intake.
- Separate urgent deterministic cases from uncertain routine work.
- Invoke manual-only or queue-and-replay mode.
- Escalate when age or volume crosses a fixed boundary.
Do not increase throughput by ignoring policy gates or bulk-assigning tickets to an unverified destination.
Prioritize with stable evidence
Fallback priority should use facts that remain valid during degraded operation.
Useful inputs include:
- Existing ticket priority and contractual target
- Protected category or service
- Known business impact
- Age since intake and fallback admission
- Presence of an accepted owner
- Deterministic incident correlation
- Time until a response or resolution deadline
Treat model confidence as an admission or review signal, not a direct measure of business severity. A high-confidence routine ticket can be less urgent than a low-confidence security report.
Show the reason for the resulting order. Operators should be able to distinguish a critical ticket from an old but low-impact item.
Prevent duplicate work and queue cycling
Fallback queues often interact with retries, human assignment, and upstream reprocessing. Without state controls, the same ticket can appear in several worklists.
Use a stable fallback record keyed to the ticket and routing episode. Before an operator acts, verify the current ticket state. Close or supersede the fallback record when:
- A human has assigned the ticket safely.
- The ticket was merged or closed.
- The missing context arrived and a new decision superseded the old one.
- The destination became valid and controlled replay succeeded.
- An incident workflow took ownership.
A ticket that repeatedly leaves and re-enters fallback needs investigation. Track admission count and reason transitions. If it crosses a configured boundary, stop automated release and require review.
The controls in How to Detect and Stop AI Ticket Routing Loops apply when fallback becomes one node in a repeated assignment cycle.
Design controlled release criteria
Do not release tickets because the dependency appears healthy. Define evidence for each admission reason.
Examples:
- Low confidence: an authorized reviewer selects and records a destination.
- Missing context: required information is present and a new decision is produced.
- Invalid mapping: the destination passes active, permission, and ownership checks.
- Execution failure: platform health is restored and current state is reconciled.
- Scoped containment: an incident owner approves staged restoration.
- Hop limit: a human accepts ownership or changes the governing definition.
Before release, recheck current owner, ticket status, policy version, destination validity, and intervening human actions. Use a new decision identifier rather than mutating the failed record.
Release in bounded batches when many tickets are waiting. Stop if assignment failures, corrections, or fallback returns exceed the approved boundary.
Reconcile the queue during recovery
Build an expected population from fallback admissions and compare it with current ticket-platform state.
Classify records as:
- Waiting and eligible for review
- Ready for controlled replay
- Already resolved by a human
- Assigned but awaiting acceptance
- Closed or merged
- Blocked by a persistent dependency
- Unknown because current state cannot be verified
Keep unknown separate from waiting. If the ticket platform cannot confirm ownership, additional replay may cause duplicate or conflicting assignments.
The broader workflow in AI Ticket Routing Incident Response: A Practical Operating Framework should govern recovery authority and closure when fallback was activated by an incident.
Monitor queue health
Track the queue as an operational service:
- Arrivals and exits by reason
- Current population by priority and segment
- Oldest age and age distribution
- Time to first operator action
- Release outcomes
- Repeat admissions
- Items without an accountable owner
- Unknown execution states
- Capacity threshold breaches
- Tickets approaching service targets
Pair counts with the affected population. Ten fallback tickets from ten arrivals indicate a different condition than ten from ten thousand.
Alert on consequential states: an unowned protected ticket, a queue with no active reviewer, sustained arrival above exit capacity, or a release batch returning to fallback.
Test the fallback path
Test fallback as carefully as the primary route. Include:
- Admission for every configured reason
- Duplicate event delivery
- Human assignment before automated fallback
- Queue at capacity
- Missing telemetry
- Invalid destination repair
- Ticket closure while waiting
- Mixed eligible and ineligible recovery records
- Partial replay failure
- Repeat fallback admission
- Operator handoff across shifts
Use How to Test AI Ticket Routing Changes Before Production to include fallback behavior in release regression tests. Verify the ticket-system result and the operator view, not only the internal state transition.
Run periodic exercises for low-frequency, high-consequence modes. An untested fallback queue can fail through stale permissions, missing staffing, or an obsolete destination even when its design is sound.
Example: one resolver group becomes unavailable
A support organization retires a queue during a team reorganization, but one mapping remains active. Preflight validation rejects assignments to the retired destination.
Only tickets mapped to that resolver group enter fallback. Their records include the recommended team, invalid destination, definition version, and current priority. The fallback owner confirms that no accepted assignment exists and routes urgent cases manually while the service owner approves a replacement mapping.
After the mapping passes permission and ownership checks, operators reconcile the queue. Tickets already handled manually are marked superseded. The remaining eligible items are replayed in small batches. Monitoring confirms accepted ownership and no repeat fallback admission before the segment returns to normal mode.
Add fallback controls to governance
Fallback rules are production routing policy. Manage them through the AI ticket routing change-management framework.
Require review for changes to:
- Admission conditions
- Queue destinations and permissions
- Reason ownership
- Response targets
- Capacity thresholds
- Priority logic
- Release criteria
- Replay batch limits
- Escalation and mode-change authority
Attach representative tests and a rollback plan. A fallback change can affect every ticket precisely when the primary path is under stress.
Conclusion
A safe fallback queue is a governed temporary ownership path. It admits tickets for explicit reasons, preserves valid human work, exposes the action required, and releases tickets only after current state and recovery evidence are checked.
Keep fallback reasons, owners, capacity, and exit criteria visible. When the primary route fails, those controls prevent uncertainty from becoming lost tickets, duplicate assignments, or an unmanaged backlog.