Confidence-Based AI Ticket Triage: A Practical Governance Framework
Learn how to govern AI ticket triage with confidence bands, human review, audit controls, and feedback loops that improve routing without hiding uncertainty.
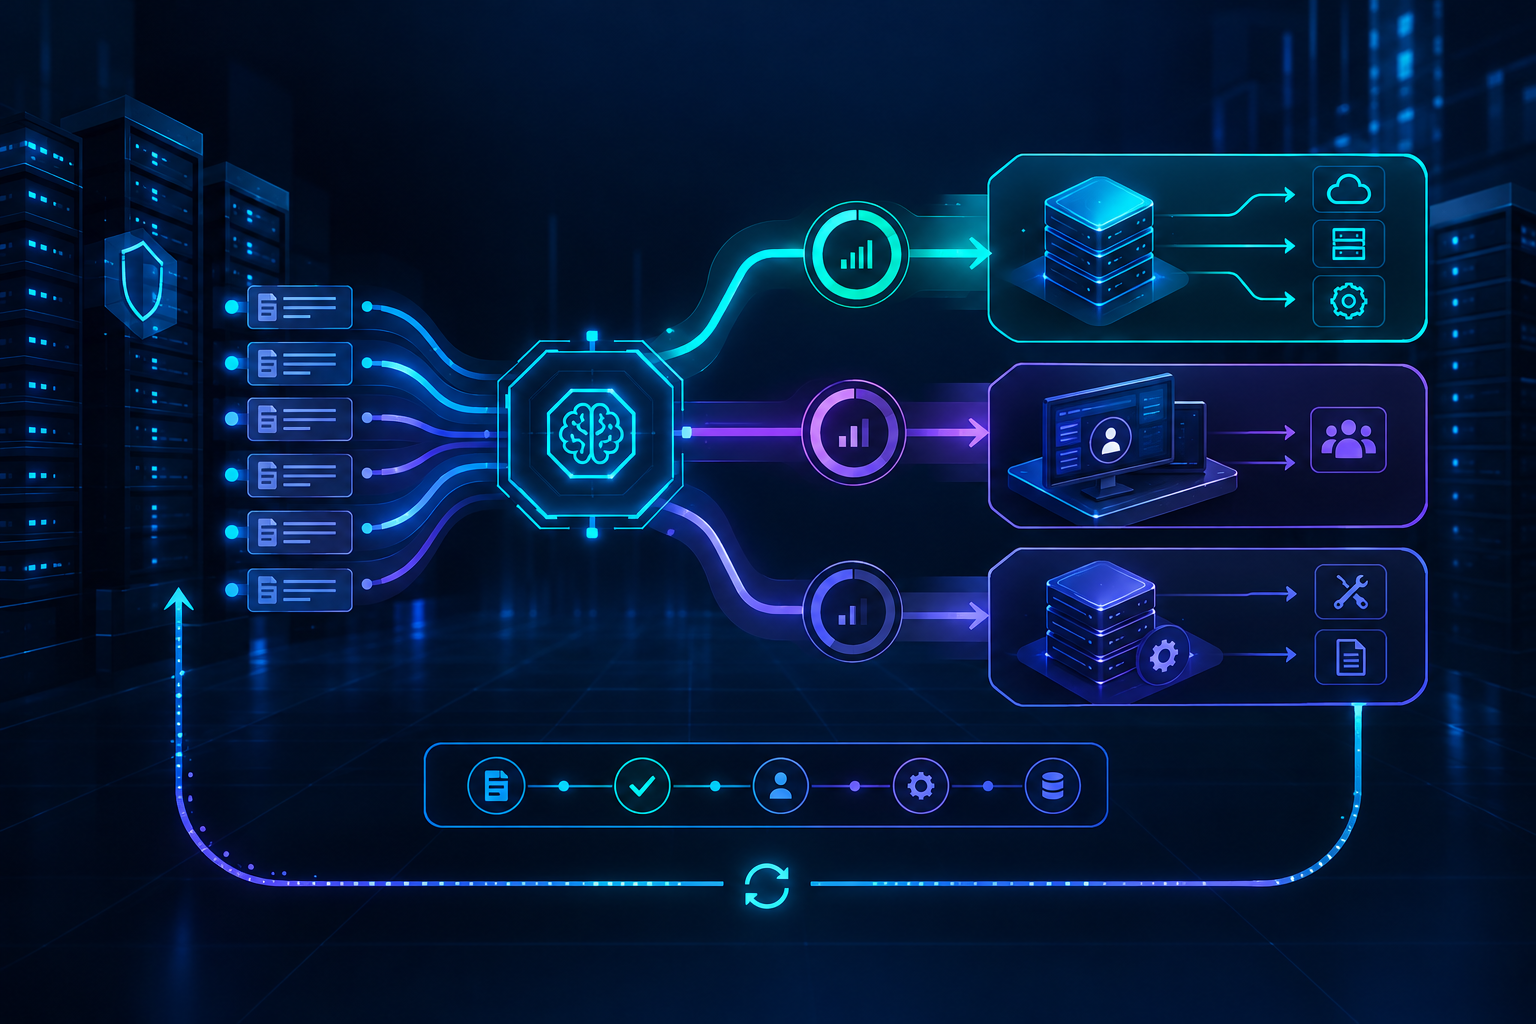
AI ticket triage becomes an operational system only when teams decide what the model is allowed to do.
A routing recommendation and a confidence score are useful outputs. They are not governance. Governance starts when the service desk translates those outputs into explicit actions: automate, request review, or stop and send the ticket to manual triage.
Without that control layer, teams tend to make one of two mistakes. They automate every prediction and create silent misroutes, or they require approval for every prediction and preserve the same intake bottleneck they wanted to remove.
This framework shows how to build the middle ground: confidence-based automation with clear ownership, exception handling, audit evidence, and a feedback loop.
What confidence-based triage governance means
Confidence-based governance is the policy layer between an AI recommendation and a workflow action.
The model may return:
- A recommended assignment
- A confidence score
- Structured classification data
- Supporting ticket signals
The governance layer decides what happens next. A simple policy can use three bands:
1. High confidence: assign automatically when all policy conditions pass
2. Medium confidence: place the recommendation in a review queue
3. Low confidence: keep the ticket unassigned and send it to manual triage
The exact thresholds should not be copied from another organization. They depend on the quality of team definitions, ticket mix, cost of a wrong assignment, and the amount of context available at intake.
For a broader view of the underlying workflow, start with the complete AI ticket triage guide. Teams still defining their classification layer should also review how to classify support tickets with AI.
Why a single threshold is not enough
A rule such as “auto-route above 80 percent” looks clean, but it ignores operational risk.
Different queues have different misroute costs
Sending a routine endpoint request to the wrong support group creates delay. Sending a suspected account compromise into a general queue can create a much more serious response gap. Both predictions can carry the same confidence score while requiring different policies.
Confidence is not the same as correctness
A score represents model certainty under a particular configuration. It is not a guarantee. Scores need to be checked against observed outcomes before they can support automation.
Ticket context changes the decision
A ticket may have a clear technical category but still require review because it comes from a sensitive user, contains security indicators, or is already close to an SLA boundary.
Team definitions drift
Queues split, responsibilities move, and escalation paths change. A model can remain technically consistent while routing against an outdated operating model.
For practical threshold design, use the companion guide on setting auto-routing confidence thresholds. It covers the rollout mechanics behind these policy decisions.
The five controls every triage policy needs
1. Defined automation bands
Document each confidence band, its permitted action, and its owner. Avoid an unowned middle state where recommendations wait without a review SLA.
A useful policy record includes:
- Confidence range
- Eligible ticket categories
- Excluded risk conditions
- Workflow action
- Review owner
- Maximum review time
- Required audit fields
This turns a score into an enforceable operating rule.
2. Risk-based exclusions
Some tickets should never auto-route on confidence alone. Common exclusions include suspected security incidents, executive-impacting requests, regulated workflows, major incident indicators, and tickets with missing identity or asset context.
The exclusion should not discard the recommendation. It should change the action from automatic assignment to review.
This is especially important for teams using early risk signals. The workflow in how to identify high-risk support tickets before they impact SLAs can supply additional gates alongside confidence.
3. A real exception queue
Medium- and low-confidence tickets need a designed path, not a generic holding queue.
The exception view should show:
- Ticket subject and relevant body text
- Recommended team
- Confidence score
- Alternative candidate teams when available
- Policy reason for review
- Current SLA state
- Approve, correct, and escalate actions
Reviewers should be able to correct the recommendation in one step. If correction requires reopening the ticket, searching for a queue, and adding a separate note, feedback quality will deteriorate.
4. Human override with reason capture
Overrides are not failures to hide. They are the most useful evidence for improving team definitions and routing policy.
Keep the reason list short enough to use consistently:
- Wrong issue category
- Correct category, wrong team
- Missing ticket context
- Team definition overlap
- Risk policy override
- Temporary ownership change
Allow a note for unusual cases, but do not depend on free text for routine reporting.
5. An auditable feedback loop
Every automated or reviewed decision should produce a small decision record:
- Model recommendation
- Confidence at decision time
- Applied policy version
- Final assignment
- Whether a human changed it
- Override reason
- Timestamp and reviewer when applicable
The goal is not to store model reasoning. The goal is to reconstruct why a workflow action occurred and determine whether the policy behaved as intended.
The long-tail guide on auditing AI ticket misroutes and building a feedback loop explains how to turn those records into operational changes.
A practical governance workflow
Consider a managed service provider routing identity, endpoint, network, and business application tickets.
Step 1: Normalize intake
The workflow sends the ticket subject and body to the triage service. It also checks whether required fields such as client, affected user, and contact channel are present.
Step 2: Generate a recommendation
The model returns “Identity Team” with a confidence score of 0.91.
Step 3: Apply policy gates
The ticket contains “unexpected MFA prompts.” The identity category is clear, but the security phrase matches a risk exclusion. Policy changes the action from auto-assignment to expedited human review.
Step 4: Review the exception
The triager confirms that the ticket should go to the Security Operations queue, records “risk policy override,” and assigns it.
Step 5: Preserve the decision
The system stores the original recommendation, score, triggered gate, final queue, and override reason.
Step 6: Review the pattern
During the weekly triage review, the team sees repeated identity-to-security overrides tied to MFA fatigue language. It updates the relevant team descriptions and tests whether the change improves separation without reducing accuracy elsewhere.
This is controlled automation: the model handles repeatable decision preparation, policy governs action, and humans resolve uncertainty.
Metrics that reveal whether governance works
Do not evaluate the program on automation rate alone. A high automation rate can coexist with poor routing.
Track a compact set of operational measures:
Auto-route precision
Of tickets assigned automatically, how many reached the correct team without reassignment?
Review acceptance rate
How often do reviewers approve the recommended team? Break this down by confidence band and category.
Reassignment rate
How many tickets move to a different team after the initial decision? Separate model-driven misroutes from changes caused by new information.
Time to assignment
Measure whether review controls create a new intake bottleneck. Report automated, reviewed, and manual paths separately.
Confidence distribution
Watch how ticket volume moves across confidence bands. A sudden shift can indicate intake changes, team-definition drift, or a new issue pattern.
Override reasons
A trend in “team definition overlap” requires a different fix from a trend in “missing ticket context.”
Rollout sequence
Start with recommendation-only mode. Capture what the model would have done, then compare it with the final assignments made by triagers.
Next, enable automation for one or two stable, low-risk categories. Keep risk exclusions and review queues active from the start.
Expand only after the automated band produces acceptable assignment quality over a representative ticket mix. When performance drops, narrow the eligible categories or raise the relevant threshold while the team investigates.
The Layer8 Triage product returns a recommended team assignment and confidence score from ticket subject and body. That makes it suitable as the decision signal inside this policy structure; the service desk remains responsible for defining workflow actions, exclusions, and review ownership.
Teams building the routing workflow itself can pair this framework with how to automatically route support tickets.
Common governance failures
Treating the score as a universal policy
A threshold that works for password resets may be inappropriate for security or production-impacting tickets.
Sending every exception to the same group
This recreates manual triage under a different queue name. Exceptions need owners and review targets aligned to category and risk.
Tuning only for more automation
Lowering thresholds increases automated volume. It does not necessarily improve throughput if reassignment and escalation work also increases.
Ignoring operational changes
Policy should be reviewed when teams, services, intake forms, or escalation rules change.
Capturing corrections without using them
Override data has value only when someone reviews recurring patterns and owns the resulting changes.
Conclusion
Confidence-based AI ticket triage is not a choice between full automation and manual control. It is a governed set of decision paths.
Define separate automation bands, add risk-based exclusions, design the exception queue, capture overrides, and review outcomes by category. That structure lets teams automate stable work while keeping uncertain or high-impact decisions visible.
Start in recommendation mode, validate outcomes, and expand automation one controlled segment at a time. The result is a triage system that can move faster without treating confidence as certainty.