Vulnerability Scanner Health Monitoring: An Operational Guide
Build vulnerability scanner health monitoring around scope, assessment depth, execution, identity, and evidence delivery instead of relying on job status alone.
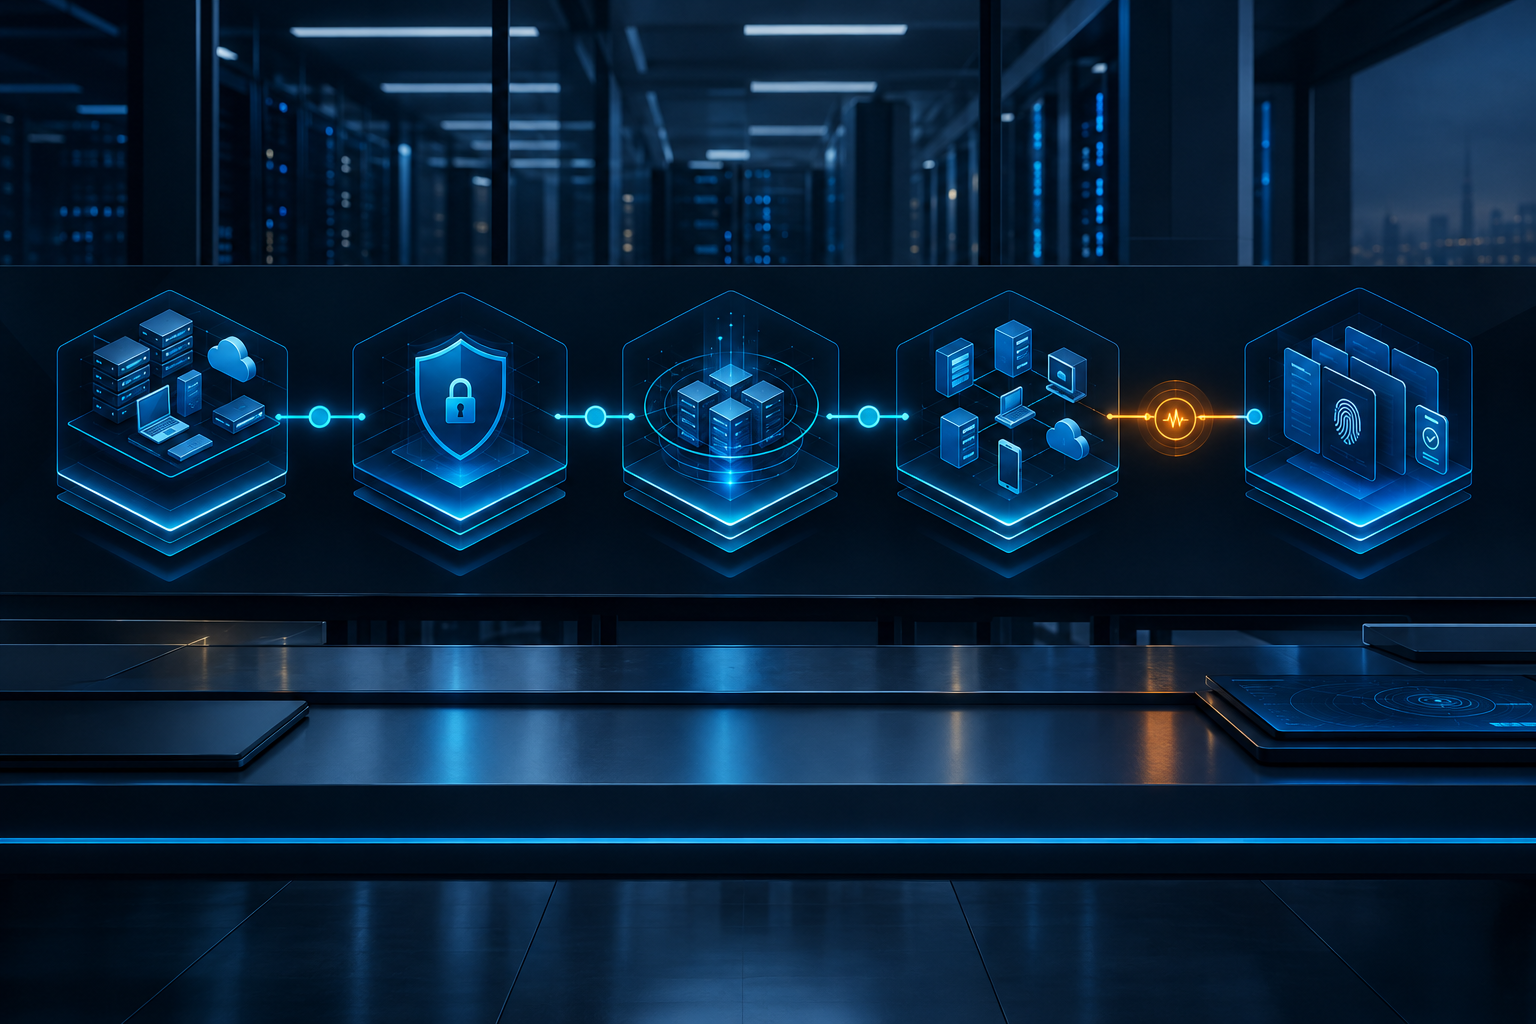
A vulnerability scanner can report a completed job while the underlying control is unhealthy. Targets may be missing, credentials may fail, required checks may not run, results may attach to the wrong assets, or findings may never reach the operating queue.
Scanner health monitoring must therefore evaluate the production of trustworthy evidence, not only scanner uptime and job completion. This guide defines an operating model for that work. It extends the complete vulnerability scanning guide, complements vulnerability scan coverage management, and can be coordinated through Layer8 Sentinel.
The supporting workflows explain how to detect silent vulnerability scan failures and how to define vulnerability scanner health SLOs.
Define scanner health as an evidence chain
A healthy scanner produces current, complete, correctly associated, and actionable evidence for every required asset-method pair.
That outcome depends on five linked control stages:
1. Scope: Expected assets resolve into the intended target population.
2. Depth: The required assessment method, credentials, privileges, and check families apply.
3. Execution: The correct scanner perspective reaches the target and completes within the required interval.
4. Identity: Results attach to the correct asset and lifecycle record.
5. Delivery: Findings, failures, and supporting evidence reach the systems and owners that act on them.
A green status at one stage does not compensate for failure at another. A scanner may be available while its cloud connector is stale. A job may complete against every resolved target while the selection rule omits a production account. A host may return results while credentialed checks never execute.
Represent health at the asset-method level wherever possible. “Server scanned” is ambiguous when policy requires both an external exposure assessment and credentialed host inspection.
Establish the expected state
Monitoring requires an explicit reference state. Start with the control-focused process in How to Baseline Vulnerability Scanner Configuration. The baseline should describe expected behavior, not merely preserve a console export.
For each managed asset class, record:
- Authoritative inventory source
- Eligibility and exclusion rules
- Required assessment methods
- Maximum evidence age
- Required scanner perspective
- Authentication and privilege expectations
- Mandatory check families
- Stable identity keys
- Evidence destination
- Control owner and escalation path
- Approved exception mechanism
Convert those requirements into expected asset-method records. A production Linux instance might require weekly credentialed host evidence from an internal worker and daily external exposure evidence if it has a public endpoint. A container image might require assessment by immutable digest before promotion.
This expected-state set is the denominator for health monitoring. Scanner target counts are observations, not the denominator, because the scanner cannot report assets it never selected.
Monitor the five health layers
Scope health
Compare authoritative inventory with resolved scanner targets and recent results. Detect:
- Eligible assets absent from target resolution
- Unexpected assets entering production scope
- Newly created assets that miss their onboarding window
- Retired assets that continue to consume scope
- Approved exceptions that have expired
- Asset classes with no applicable policy
- Dynamic selectors whose resolved populations change unexpectedly
Use stable identities and preserve the reason each asset is expected. The reconciliation workflow in How to Reconcile Vulnerability Scan Targets with Asset Inventory provides the detailed comparison pattern.
Monitor both absolute mismatches and changes in composition. A stable count can hide one omitted asset and one unintended replacement.
Assessment-depth health
Confirm that expected methods ran at the required depth. Useful signals include:
- Authentication success by asset class and credential object
- Privilege or local inspection success
- Required check families executed
- Ports, services, packages, or configuration domains inspected
- Safe-check or throttling settings that reduced depth
- Unauthenticated fallback where credentialed evidence was required
- Method substitutions that do not satisfy policy
Treat partial results as explicit states. A host that responds to discovery but rejects authentication is reachable, not healthy.
Execution health
Observe whether the intended scanner path can perform the assessment within its operating window.
Monitor:
- Scheduled and event-driven jobs started
- Expected targets resolved at job start
- Worker pool and source perspective used
- Queue delay
- Connection and timeout patterns
- Partial completion
- Retry behavior
- Maintenance-window skips
- Last successful required assessment
- Scanner capacity near operational limits
Separate platform availability from control execution. A worker can be online yet unable to route to one network zone. A scheduler can run while an integration stops creating jobs for new assets.
Identity health
Identity defects can make fresh evidence look stale or make old evidence appear current.
Check for:
- Multiple active scanner records for one authoritative asset
- One scanner record associated with several active assets
- Results keyed only by reused IP addresses
- Hostname changes that create duplicate histories
- Cloud instance or image identifiers lost during ingestion
- Retired records receiving new results
- Merge or deduplication changes after platform updates
- Findings transferred between assets without review
Monitor identity exceptions as operational defects. They affect ownership, aging, remediation history, and closure decisions.
Evidence-delivery health
A scan is not operationally effective until its output reaches the intended workflow.
Verify:
- Result ingestion completes
- Required evidence fields are present
- Finding status maps correctly
- Timestamps preserve assessment time
- Asset and owner associations survive integration
- Suppression and exception states remain authorized
- Failed assessments produce visible work
- Queue delivery and acknowledgement occur
- Retention supports investigation and verification
Use synthetic or controlled test records where safe. They can prove that evidence traverses the full path without waiting for an organic finding.
Build layered detection
No single signal describes scanner health. Use three detection layers.
Configuration comparison
Compare effective scanner and integration settings with the approved baseline. This catches changed selectors, worker assignments, credential references, check policies, identity rules, and delivery mappings.
Follow Vulnerability Scan Configuration Drift Management: An Operational Guide to separate approved changes from unauthorized or expired states.
Outcome reconciliation
Compare expected asset-method records with recent valid evidence. Outcome reconciliation finds defects that configuration comparison cannot, including upstream inventory failures, runtime authentication errors, and results lost after execution.
For every missing record, identify the first failed stage in the evidence chain. That classification routes the problem to the team able to correct it.
Canaries and boundary tests
Maintain representative assets or safe tests for important control paths. Include boundary conditions such as:
- A newly created dynamic asset
- An asset in each network zone
- Each credential class
- A required external perspective
- A representative integration destination
- A controlled authentication failure
- An expired test exception
Canaries should validate an actual control path. A dedicated test host proves little about a production selector if it is manually added to scope.
Design the operating workflow
Detect and open a health incident
Create a health incident when a threshold, invariant, or freshness objective is breached. Record the affected asset-method population, failed stage, first observed time, last known healthy evidence, and current owner.
Do not wait for a vulnerability count to fall. Fewer findings may indicate improvement or missing assessment depth.
Bound the impact
Resolve which assets, methods, jobs, findings, and closure decisions could be affected. Determine when the condition began and whether it is ongoing.
Prioritize internet-facing and critical systems, broad dynamic selection failures, authentication loss, and evidence defects that could produce false closure.
Contain safely
Containment may include restoring a prior configuration, rerouting jobs, pausing automated closure, replacing a failed credential, running a controlled assessment, or narrowing an invalid exception.
Account for production constraints. A sudden broad rescan can overload a fragile service or scanner pool. Use a staged recovery where needed.
Correct the failed control
Fix the earliest failed stage, not only the visible symptom. Re-running a job does not repair a broken inventory connector. Re-ingesting results does not correct an identity rule that attaches them to the wrong asset.
Assign root cause to the control path: source inventory, selection logic, scanner policy, credential service, worker routing, identity resolution, or evidence integration.
Verify recovery
Recovery requires fresh evidence. Confirm that:
1. Expected assets resolve into scope.
2. Required methods and depth apply.
3. The intended perspective completes.
4. Results attach to correct identities.
5. Evidence reaches the operating queue.
6. Exceptions and temporary recovery changes are closed.
7. Related populations governed by the same control are checked.
For recurring health failures, use the focused silent scan failure detection workflow to add a durable detector rather than relying on operator memory.
Assign ownership
Scanner health crosses platform, infrastructure, identity, network, and vulnerability operations teams. Define ownership by control stage.
A practical model assigns:
- Asset owners to authoritative inventory and lifecycle data
- Vulnerability platform owners to policy, scheduling, workers, and integrations
- Identity or secrets owners to credential availability and rotation
- Network owners to scanner reachability
- Vulnerability operations to health reconciliation and incident coordination
- Risk owners to exceptions and accepted evidence gaps
Every alert needs one coordinating owner even when several teams participate. Avoid routing all failures to asset owners; they often cannot fix scanner selection or integration defects.
Measure control health
Useful measures include:
- Expected asset-method pairs with current valid evidence
- Pairs missing evidence by failed stage
- Time from health breach to detection
- Time from detection to restored evidence
- Authentication success for methods that require it
- Jobs with partial or substituted depth
- Identity conflicts awaiting correction
- Evidence-delivery failures
- Exceptions past expiration
- Repeat incidents by control path
Counts need context. Report affected criticality, exposure, owner, and evidence age so operators can act.
Translate these measures into owned objectives with How to Define Vulnerability Scanner Health SLOs. SLOs should express the evidence outcome and the response expected when it is missed.
Example: healthy jobs, missing cloud account
A cloud connector loses authorization to enumerate one production account. Existing scan policies continue to run and complete against targets from the remaining accounts. Job success remains green, and the total target count changes only slightly.
Expected-state reconciliation identifies production instances without recent credentialed evidence. The health incident is classified at the scope stage. The team restores connector authorization, confirms the account resolves into target groups, runs controlled assessments, validates authentication and result delivery, and reviews closure decisions made during the gap.
The durable correction monitors account enumeration against the approved organization inventory and alerts when an expected account produces no eligible assets. Monitoring only scanner jobs would not detect the defect.
Conclusion
Vulnerability scanner health is the condition of the entire evidence chain: scope, depth, execution, identity, and delivery.
Define expected asset-method evidence, compare configuration and outcomes, test important control paths, and open owned incidents when health objectives fail. This operating model exposes silent control failures before they become long-lived coverage gaps and gives teams a precise path from detection to verified recovery.