How to Troubleshoot Credentialed Scan Failures and Coverage Gaps
Diagnose credentialed scan failures by separating inventory, reachability, authentication, authorization, and inspection defects.
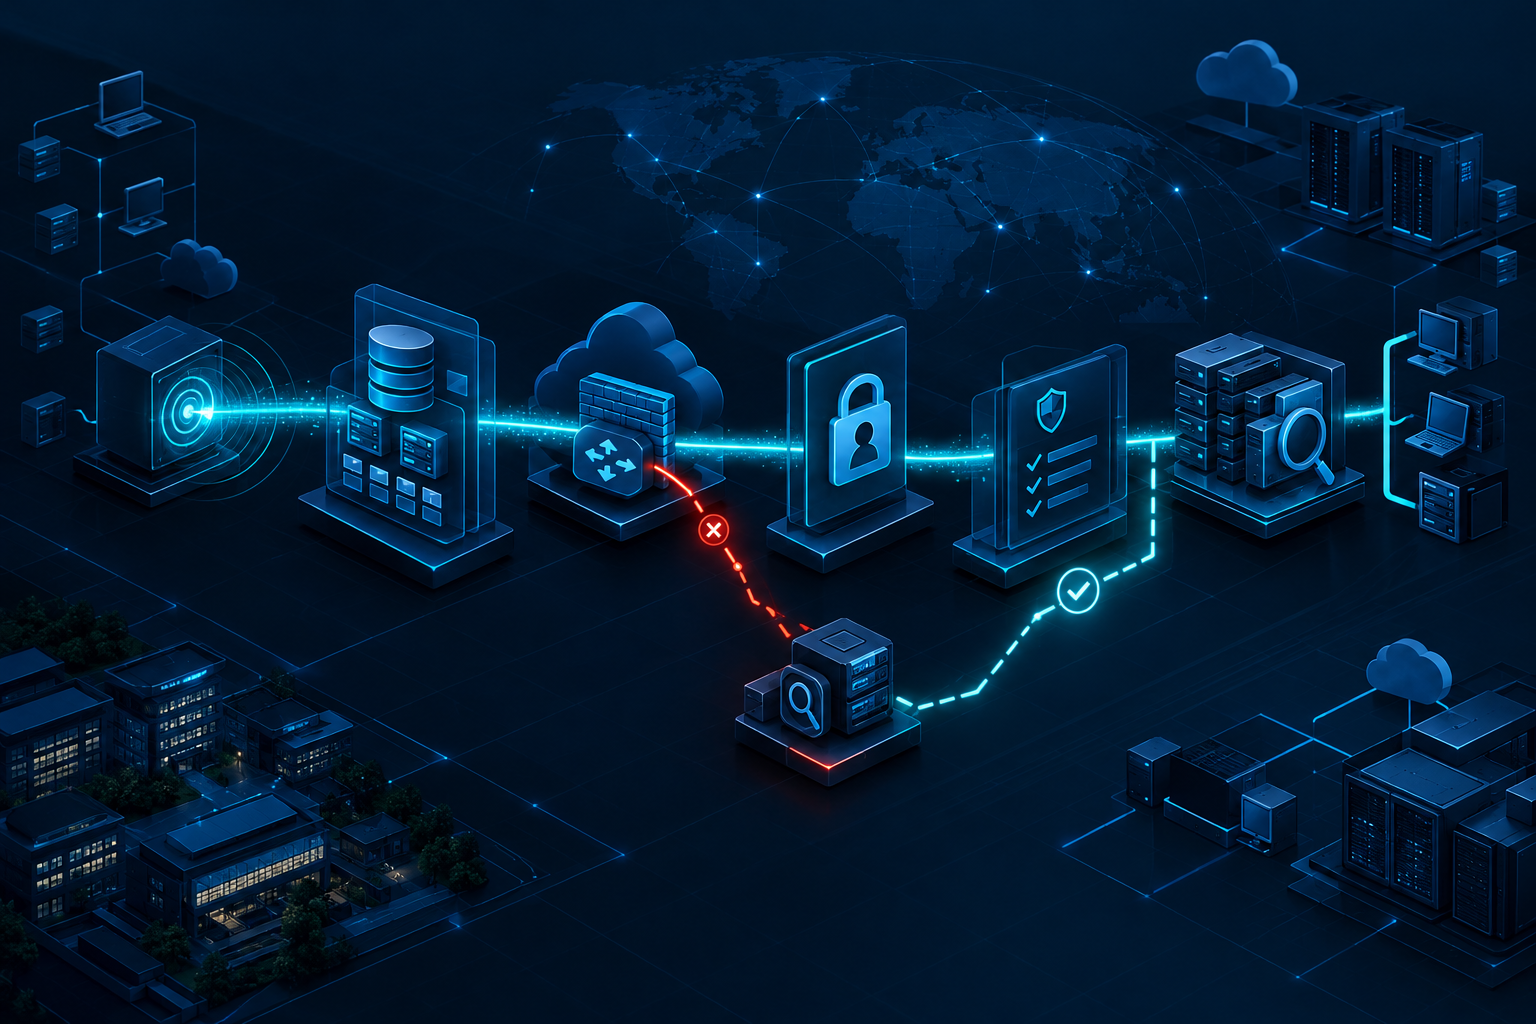
A credentialed scan can finish without producing trustworthy credentialed evidence.
The target may be reachable while authentication fails. Authentication may succeed while local permissions block important checks. A complete scan job may omit newly created assets because target generation failed. These are different defects, and each needs a different owner.
This guide provides a diagnostic sequence for separating network, identity, authorization, inspection, and inventory failures. It also shows how to restore coverage without hiding the gap behind exclusions.
For the operating model around these diagnostics, read Credentialed Vulnerability Scanning for Hybrid Environments. For foundational scanning strategy, use the complete vulnerability scanning guide, and review Layer8 Sentinel for continuous vulnerability detection and remediation guidance.
First, prove what failed
Do not begin by repeatedly rerunning the scan. Collect evidence from four places:
- Expected asset inventory
- Scanner target and job logs
- Network or access-control telemetry
- Host authentication and authorization logs
Use a stable asset identifier to correlate them. Hostnames and addresses may change between inventory generation and scan execution.
Classify the outcome before assigning the ticket:
1. Asset was not in the target set.
2. Asset was targeted but not reached.
3. Asset was reached but not authenticated.
4. Authentication succeeded but privilege was insufficient.
5. Privilege was sufficient but required checks did not run.
6. Checks ran, but evidence was stale or mapped to the wrong asset.
This classification prevents a network team from receiving an expired-secret problem or a scanner operator from receiving a firewall problem.
The discovery controls in How to Detect Exposed Services in Your Infrastructure can help compare externally visible services with expected management paths. The drift patterns in How to Detect Misconfigured Services in Your Infrastructure provide additional context for service-state changes that break inspection.
Step 1: Verify target inclusion
Before testing ports or credentials, confirm that the asset was actually scheduled.
Check inventory timing
Determine when the asset entered the authoritative inventory and when the scanner generated its target set. Short-lived or recently created workloads may exist after a scheduled export.
Check filters and exclusions
Review environment tags, address ranges, cloud-account selection, operating-system filters, and exception rules. Look for:
- A changed tag value
- An expired but still active exclusion
- A new subnet outside the target range
- A cloud account not connected to inventory
- Duplicate records collapsed onto the wrong identifier
- A retired record selected instead of its replacement
Check worker assignment
Confirm that the target was assigned to a worker that can reach its network zone. A valid target sent to the wrong worker is an orchestration failure, not a host failure.
If the asset was omitted, correct the inventory or scheduling path and create a fresh target set. A manual one-off scan can validate the asset, but it should not substitute for repairing the source process.
Step 2: Verify network reachability
If the asset was targeted, test the exact path used by the scanner worker.
Use the worker perspective
A successful connection from an administrator laptop does not prove scanner reachability. Test from the designated worker or through equivalent telemetry.
Confirm:
- Name resolution returns the expected address
- Routes select the expected interface or gateway
- Security groups and firewalls allow the required path
- Network access controls permit return traffic
- Proxies or gateways support the protocol
- The management service is listening
- Source restrictions include the current worker addresses
The Linux scanning workflow in How to Scan Linux Servers for Vulnerabilities helps define the host and network prerequisites for that platform.
Distinguish timeout, refusal, and protocol failure
A timeout suggests filtering, routing, or an unavailable host. A refusal suggests the host is reachable but no service accepted the connection. A protocol negotiation failure points toward service configuration, versions, ciphers, certificates, or intermediaries.
These are starting hypotheses, not final proof. Correlate them with firewall and host logs.
Step 3: Verify authentication
Once the management service is reachable, determine whether the supplied identity was accepted.
Check secret selection
Confirm that the job used the intended credential mapping for the asset's environment, platform, and zone. Template inheritance can silently apply a non-production or old credential.
Check secret state
Verify:
- The vault version is current
- The scanner retrieved that version
- The account is enabled
- The secret or certificate has not expired
- The account is not locked
- The key or certificate is trusted by the target
- Clock synchronization is within protocol tolerance
Do not reveal secrets in tickets or logs while testing.
Check identity policy
Review authentication-source restrictions, login-hour controls, conditional access, SSH policy, and permitted logon types. A policy change may reject a previously valid scanner without changing the secret.
If scan accounts need redesign, use How to Design Least-Privilege Scan Accounts for Credentialed Vulnerability Scanning to set boundaries and a check-level validation method.
Step 4: Verify authorization
Authentication proves identity, not inspection rights.
Look for scanner warnings and host audit events that show:
- Permission denied when reading package or patch state
- Registry or policy paths that cannot be queried
- Elevation commands not allowed
- Service-control or management interfaces denied
- Mandatory access control blocking an otherwise permitted read
- Endpoint protection intercepting scanner activity
Map each denial to an enabled check and approved evidence requirement. Do not solve a single denied read by granting unrestricted administrator access.
Change one permission at a time, rerun the affected checks on a representative system, and preserve the before-and-after evidence.
Step 5: Verify the inspection layer
The identity can be valid and sufficiently privileged while inspection still fails.
Check platform support
Confirm that the scanner recognizes the operating-system version, package manager, architecture, and enabled modules. A new OS image or package format may require an engine or plugin update.
Check host dependencies
Some checks depend on local services, management frameworks, interpreters, or command paths. Compare the affected host with a known-good peer on the same baseline.
Check scanner health
Review worker capacity, update state, plugin load errors, timeouts, and resource limits. If many unrelated targets fail at the same stage and time, investigate the shared scanner layer.
Check scan policy
A policy edit may disable credentialed checks, shorten timeouts, change safe-check behavior, or exclude a platform family. Compare the current version with the last known-good policy.
Step 6: Detect partial coverage
The most dangerous status is often "authenticated" with incomplete evidence.
Build required check groups for each platform, then verify that every group produced recent evidence. Examples include:
- Operating-system and kernel identification
- Package or patch inventory
- Service configuration
- Local security policy
- Required application components
Flag assets where authentication succeeded but one or more required groups did not complete. Report these separately from total authentication failures.
A compact diagnostic decision tree
Use this sequence during triage:
- Missing from target? Repair inventory, filter, exclusion, or scheduling logic.
- Targeted but unreachable? Repair DNS, route, firewall, worker placement, or host service.
- Reached but rejected? Repair credential mapping, secret state, account lockout, trust, or identity policy.
- Authenticated but denied? Repair the least-privilege role or host policy.
- Authorized but checks missing? Repair platform support, scanner health, dependencies, or scan policy.
- Evidence present but stale or misattributed? Repair asset correlation and freshness rules.
Assign one primary failure class and capture contributing factors separately.
Example: a false recovery
A cloud Linux group fails credentialed scans after a key rotation. An operator updates the scanner and reruns one host successfully, then closes the incident.
The next scheduled window still fails on half the group. Investigation shows that two worker pools use separate secret integrations; only one retrieved the new key version.
The correct recovery process is:
1. Identify every worker and credential mapping in scope.
2. Confirm the same approved secret version is available to each.
3. Test one representative host per worker and network zone.
4. Run the full affected target set.
5. Reconcile successful check-level evidence against expected assets.
6. Revoke the old key after validation.
7. Close the coverage incident with the reconciliation record.
A successful spot check was useful, but it was not proof of restored coverage.
Route and prioritize coverage incidents
Prioritize a coverage failure using:
- Asset criticality
- Internet exposure
- Age of the last valid credentialed evidence
- Number of affected assets
- Whether the failure crosses a shared image, identity, network, or worker
- Whether active remediation depends on a validating rescan
A shared identity failure affecting a production zone deserves different handling from one retired test host. Define response targets for coverage incidents just as you do for vulnerabilities.
Route by broken dependency:
- Inventory integration: asset or cloud platform team
- Network path: network or cloud networking team
- Credential or account policy: identity team
- Local role: operating-system or platform team
- Scanner engine and policy: vulnerability management team
- Unsupported application or OS: service owner with risk governance
Prove recovery
Close a coverage incident only when new evidence shows:
- The correct asset was targeted
- The intended worker reached it
- The expected identity authenticated
- Required privilege-dependent checks ran
- Evidence freshness meets policy
- The asset maps to the correct owner and environment
- The next scheduled path is repaired, not bypassed
Attach references to logs or scan evidence without copying credentials or sensitive host data into the ticket.
Prevent repeat failures
Turn recurring defects into platform controls:
- Alert before credential and certificate expiry
- Test scan roles in base-image pipelines
- Validate scanner routes after network changes
- Reconcile cloud inventory before each scan window
- Canary-test scanner and plugin updates
- Monitor authentication success and required check groups separately
- Review exceptions and exclusions with expiration dates
- Track failure age and recurrence by root cause
Conclusion
Credentialed scan troubleshooting is an evidence problem before it is a scanner problem.
Prove target inclusion, reachability, authentication, authorization, and check execution in that order. Separate complete failure from partial inspection, route the defect to the owner of the broken dependency, and require a representative rescan plus inventory reconciliation before closure.
When coverage failures are handled as control incidents, vulnerability reports become more trustworthy and remediation validation stops depending on assumptions.